What makes a picture animate well

Models continue what they see, including its problems. In our six running-commercial takes, a crowded, visibly synthetic starting frame stayed questionable however good the prompt was, and a wider, more believable frame gave the same model something to work with. Before generating, check your picture for these:

  • Room to move. A subject jammed against the frame edge has nowhere to go. Leave space in the direction of travel.
  • Faces with enough pixels. Small faces get redrawn badly. Generate wider, then crop in, or use a closer picture.
  • Believable light. One clear light source survives motion better than flat or mixed light.
  • No clutter you do not want animated. Everything in the frame is a candidate to move, melt or multiply.

Example 1: a generated still into a race shot

The same starting frame and identity sheet went to several models. This is the selected take: Seedance 2.5 in Dreamina, 5 seconds at 480p. It was a draft, and the timed direction made the sideways camera move, the facial effort and the rivalry read clearly.

Input

Starting frame
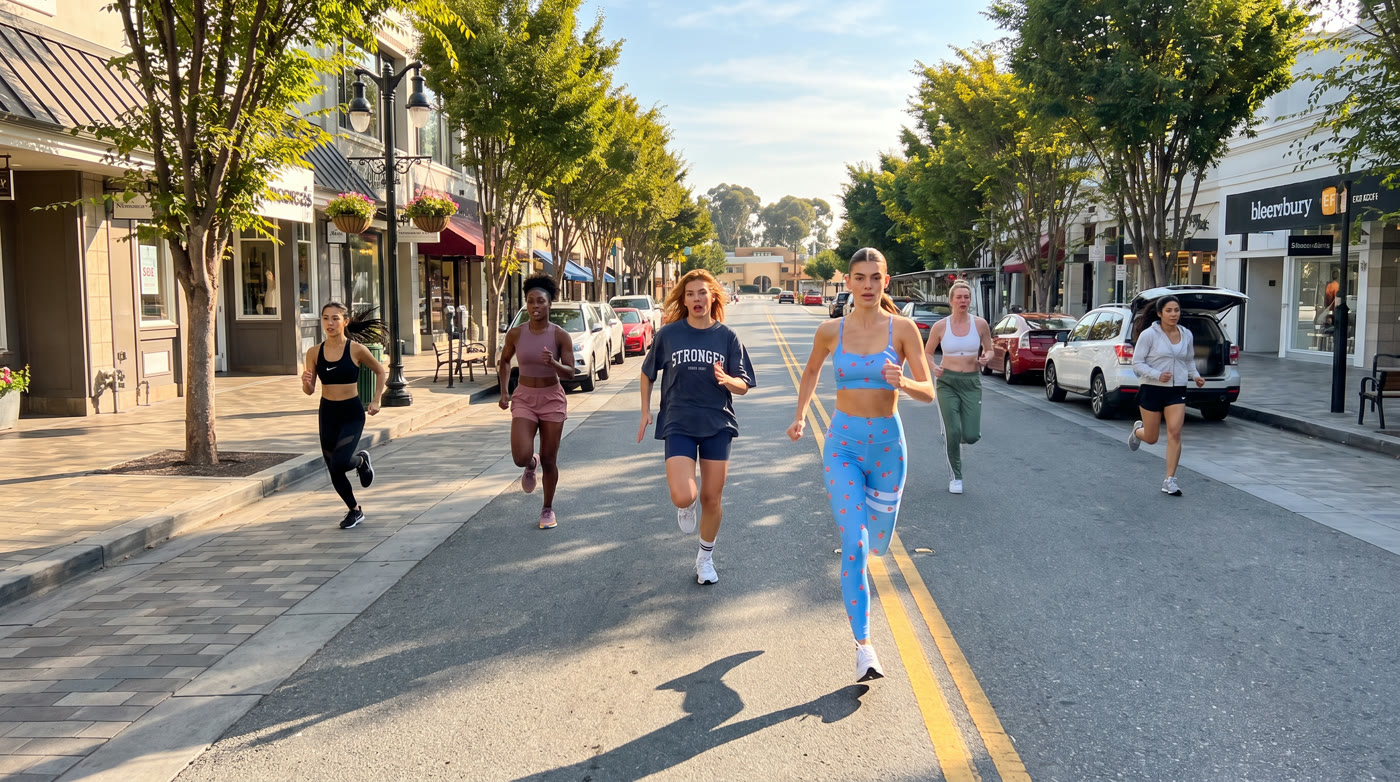
Starting frame of six women running down a sunlit shopping street

A wide street, late sun and a clear path for the pack. Faces and outfits came from a separate sheet.

Output · 5 s

Seedance 2.5

The camera moves to the side of the leaders and the effort is visible. It is still a 480p draft.

Example 2: first and last frame, for exact timing

If you need the shot to land on a specific composition, give the model both ends. Wan 3.0 on Higgsfield took the two pictures and produced 3 seconds at 1080 × 1920 and 30 fps with sound, for 10.5 credits. The prompt describes only what happens between them. The model honoured both frames, and the trader never looks up, which is what the prompt asked for.

Input

First frame
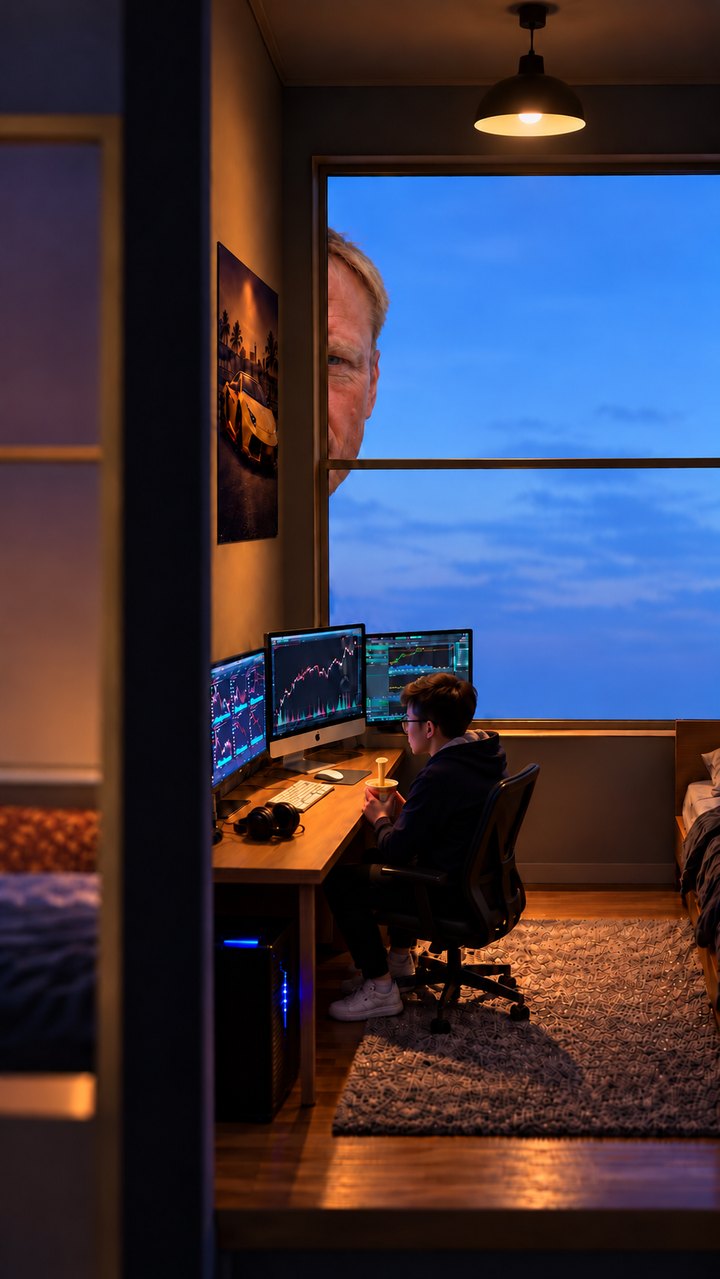
Miniature trader at a desk with the edge of a giant face at the window

The last frame is the same room with the whole face filling the window.

Output · 3 s

Wan 3.0

The trader keeps eating; the giant slides in and settles on the final frame.

Example 3: a portrait photo that talks

For a real person’s photo with a real voice, an avatar model is the direct route. Kling AI Avatar v2 Pro took one photo and 5.55 seconds of recorded speech, cost $0.83 on fal and took 7 minutes. It kept the freckles and skin texture, and every gesture is invented, so use this for a new piece to camera. To keep a real recorded performance, video edit works better. Only animate a real person with their consent.

Input

Source photo
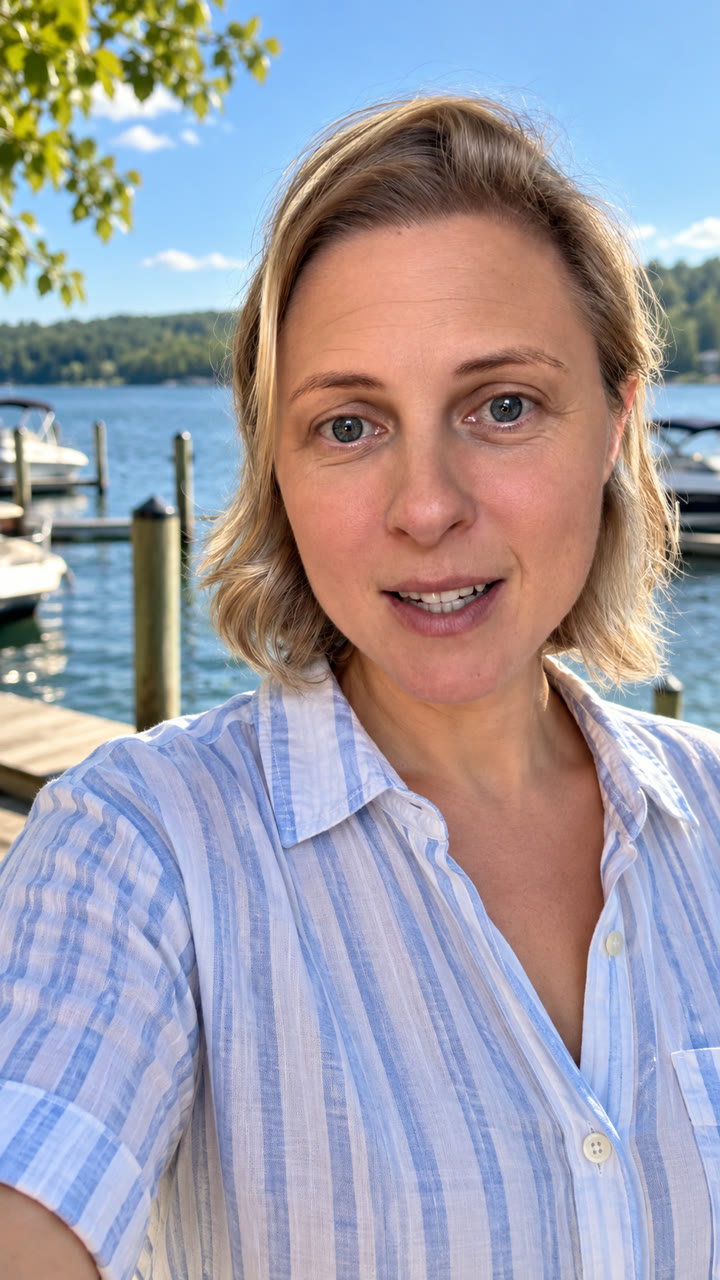
Portrait photo of the speaker at a lakeside marina

One photo, plus the speaker’s own recording.

Output · 5.55 s

Kling AI Avatar v2 Pro

Close to the photo, with a believable hand-held sway. The clip plays silent here.

How to animate a photo, step by step

  1. Fix the picture first. Edit it until it is right. A picture edit costs about $0.15 on Nano Banana Pro at 1K, against dollars for video.
  2. Match the output format. Use the same aspect ratio as the video you want, or the model may crop it. Our MiniMax H3 setup silently dropped to a smaller canvas when the frame ratio did not match exactly.
  3. Write the motion, not the picture. “She looks up from the phone and smiles. The camera pushes in slowly.” Say what stays the same in a few words.
  4. Ask for one move per few seconds. Short shots have room for one small move.
  5. Run a cheap test. Draft at 480p or 720p. Keep the same model mode you will use for the final.
  6. Check at full size. Look at faces, hands, text and whether the person still looks like themselves, before you pay for 1080p.

Which image-to-video model should you use?

From our own runs. Prices are list prices for 5 seconds, captured 2 November 2026.
NeedModel720p1080pWhat we saw
Lowest priceWan 3.0, API$0.50$1.00Followed first and last frames well; cannot mix them with reference pictures on Higgsfield
One unbroken shot with actionSeedance 2.5, BytePlus≈ $1.16≈ $2.84Strongest race direction; long negative lists pushed it into slow motion
Several referencesKling 4.0, API≈ $0.79≈ $1.18Takes reference pictures and always adds sound

Free image-to-video options

Searching for a free image-to-video generator is reasonable for a first try. Adobe Firefly lists free daily generations, and Canva allows Image to Video while your monthly AI allowance lasts. Google Flow’s daily credits are what we used for tests. The full free-plan table shows the watermarks and limits. Expect to pay once you need 1080p, no watermark or commercial rights.

For several shots with the same person, keep going with the consistency guide.

Learn this on your own shots

The workshops take you from one picture to a finished video in three hours, with your own material.

Find your workshop ↗

Take 06 · Dreamina Seedance 2.5

Prompt used for this take

runnig6_street_race_16x9_v3 is the first frame of the video: the street, camera position, sunlight and the position of every runner at 0.0s.

six_women_sheet_2 is the identity and wardrobe reference only: the faces, hair, bodies, outfits and shoes of the same six women, top row left to right: 1 the brunette with a slicked-back ponytail in the light blue strawberry-print STRONGER sports bra and leggings, 2 the copper-haired woman in the washed navy oversized STRONGER t-shirt and bike shorts, 3 the woman in black Nike, 4 the ash-blonde in the white adidas top and sage green track pants, 5 the woman in the mauve HOKA top and pink shorts, 6 the woman in the open grey New Balance jacket. Take only the people from six_women_sheet_2; its grey backdrop, flat studio light and side-by-side lineup stay out of the video. Every woman keeps her exact face and outfit from six_women_sheet_2 throughout, with a stable, recognisable face. 16:9.

Side-tracking shot down a shopping street. Light, exactly as in runnig6_street_race_16x9_v3: the only light is the late-afternoon sun, low in the sky at the far end of the street and slightly to the right, about 15 degrees above the horizon behind the runners. It is hard, direct sunlight with crisp shadows, warm golden in colour, while the shade stays cool and slightly blue. It rims the runners' hair, shoulders, arms and calves with a bright warm edge that separates them from the street, and throws long hard shadows from their feet toward the camera and slightly left. The fronts of their bodies and their faces are on the shadow side, one to two stops darker, lit only by soft warm bounce from the pale asphalt, with natural skin micro-texture and subtle pores. When the camera reaches their side, the same sun comes from the right edge of the frame, behind them: the backs of their heads, shoulders and calves glow, their faces turned toward the left of the frame stay in soft bounce light, and their shadows stretch ahead of them across the asphalt. Fine dust kicked up by their shoes catches the backlight. The sun does not move and the exposure does not change during the camera move; only the dappled shadows of the street trees slide over the runners as they pass under them.

The video starts exactly on @Image1: six women racing hard straight toward the camera down the middle of the street. Over the first 1.5 seconds the camera swings from this front view around to the right side of the frame, the runners' left side, dropping to chest height and moving in close, then travels parallel with them for the rest of the shot, moving with the group but slightly slower so they pull forward through the frame. They cover about twenty-five metres of the street, so the background travels more than two full frame widths: the storefronts, lamp posts with hanging flower baskets and parked cars from the opening frame leave the edge within two seconds, and three or four shopfronts, street trees and parked cars that were never in the opening frame sweep in and pass behind them.

Breathing and faces: every runner breathes in a real running rhythm synced to her stride, a quick inhale with lips nearly closed, then a hard exhale through an open mouth, every second step, so mouths keep opening and closing instead of staying open. Their expressions change as the race tightens: eyebrows pull together, jaws clench, lips press into a line before a push, cheeks puff on a sharp exhale, eyes flick sideways at the rival next to them.

[0:00-1:50] The pack runs toward the camera as in runnig6_street_race_16x9_v3, backlit, while the camera swings to their side. The lead in the strawberry-print STRONGER set breathes steadily, face focused, lips closing between exhales.
[1:50-2:50] The camera is beside them; the lead runs closest, filling half the frame height, the sun rimming the back of her ponytail and shoulders. The copper-haired runner in the navy STRONGER t-shirt glances at her, presses her lips together, then surges up to her shoulder with a sharp exhale through gritted teeth.
[2:50-3:50] They pass under a street tree and leaf shadows slide across their faces and arms, then warm sun hits their backs again. The lead feels the rival there: her brow tightens, her jaw sets, and she drives her arms harder with a short, strong exhale. Behind them the runner in the mauve HOKA top and the blonde in green track pants push hard, faces straining, mouths opening wide on each breath.
[3:50-5:00] The two STRONGER runners are level, stride for stride, passing a new corner shopfront; both faces show the last extra effort, eyes narrowed, nostrils flaring on the inhale, mouths snapping open on each exhale. Full racing speed, fast leg cadence, arms driving hard, ponytails and hair whipping backward and glowing in the backlight, faces sharp, clothing and printed logos readable, heavy speed blur across the buildings, parked cars and pavement while the runners stay sharp.

Wan 3.0 · shot A · start frame to middle frame, 3 s

Prompt used for shot A

3-second contemporary digital comedy shot inside a physical miniature dollhouse. One continuous take: a miniature trader eats noodles at his desk while a giant, unnoticed, slowly rises into view behind his rear window.

FORMAT: 9:16, 3.0 seconds, photoreal digital cinema with native sound.

START AND END: open exactly on the supplied start frame (trader room; trader holding his noodle cup near his mouth; only a sliver of the giant observer's face visible at the far left edge of the rear window) and end exactly on the supplied end frame (same room; the observer's whole face filling the rear window, looking down at the trader). Keep both frames' composition, proportions, floor height, window geometry, furniture, desk items and lighting.

TRADER: miniature young man at the desk, glasses, black hoodie, dark trousers, white trainers. He eats continuously for the whole shot: cup held near his mouth in one hand, lifting forkfuls of noodles, chewing, eyes on his three monitors. He never notices the observer, never turns, never speaks. Black over-ear headphones lie untouched on the desk beside the keyboard.
OBSERVER: giant blond man, blue eyes, light-blue T-shirt, outside the rear window; exactly the man in the end frame. He moves from almost out of view at the left edge across and into the window, curious, settling into the end frame's head position, angle and downward gaze. Lips closed, silent, hands below the sill.

STYLE: frame-matched lens perspective, deep focus holding trader and observer together, restrained acting, natural skin and cloth. A photographed miniature set with a real person outside, not generated footage.
COLOR: warm brown and charcoal room under a warm pendant; blue daylight outside the window.
ENVIRONMENT: the trader room only: desk with three monitors, keyboard, headphones, bed, rug, wall artwork. Architecture and furniture stay fixed.

CAMERA: very slight physical dolly to camera-right along the open dollhouse front, matching the small shift between the start and end frames; constant height, direction and focal length. No zoom.

[0.0s-2.5s] The trader keeps eating - forkfuls lifted and chewed, eyes on the monitors. The observer glides in from the left edge of the rear window, his face rising and sliding across until it fills the window, quietly watching the trader eat. SFX: faint computer hum, fork against the cup, soft slurping, chewing.

[2.5s-3.0s] Held composition matching the end frame: the observer's face filling the rear window, eyes on the trader; the trader still eating, unaware. Camera settled.

AUDIO: eating sounds and computer hum only; subtle room ambience. No dialogue, no music, no narration, no on-screen text, no subtitles, no logo.

CONSTRAINTS: one unbroken take; no cuts, dissolves, black frames or zoom. Nobody speaks. The trader keeps eating and never looks at the window. The headphones stay on the desk. Preserve identities, wardrobe, miniature-to-giant scale, room dimensions, window geometry and desk items. Stable faces throughout, no morphing, no deformation, photoreal cinematic finish.

Avatars 1 and 2 · OmniHuman 1.5 and Kling AI Avatar v2 Pro

Prompt used for both avatars

A woman talks directly to the camera in a handheld selfie video on a sunny lakeside marina. Natural, relaxed delivery: small head nods and tilts, lively eyebrows, natural blinks, subtle shoulder movement, slight handheld camera sway as if she holds the phone at arm's length. Her hair moves lightly in the breeze; boats rock gently on the water behind her. Her face, hair and striped shirt stay exactly as in the photo. Realistic skin, natural daylight.

Inputs: the marina photo as the image, the speaker's own recording (0-5.55 s) as the audio. OmniHuman 1.5 at 720p.