Что заставляет изображение хорошо анимироваться

Модели продолжают то, что видят, включая ошибки. В наших шести дублях для рекламного ролика переполненный, явно синтетический начальный кадр оставался сомнительным, каким бы хорошим ни был промпт, а более широкий и правдоподобный кадр дал той же модели материал для работы. Перед генерацией проверьте изображение на наличие следующего:

  • Место для движения. Если объект прижат к краю кадра, ему некуда двигаться. Оставляйте пространство в направлении движения.
  • Лица с достаточным количеством пикселей. Мелкие лица перерисовываются плохо. Генерируйте более широкий план, а затем кадрируйте, или используйте более крупный план.
  • Реалистичный свет. Один четкий источник света лучше сохраняется при движении, чем плоский или смешанный свет.
  • Никакого лишнего визуального шума, который вы не хотите анимировать. Все в кадре может начать двигаться, плавиться или множиться.

Пример 1: превращение сгенерированного стоп-кадра в кадр с гонкой

Один и тот же начальный кадр и лист идентичности были отправлены нескольким моделям. Это выбранный дубль: Seedance 2.5 в Dreamina, 5 секунд при 480p.. Это был черновой вариант, и благодаря временным указаниям боковой проезд камеры, мимика и дух соперничества были переданы четко.

Ввод

Начальный кадр
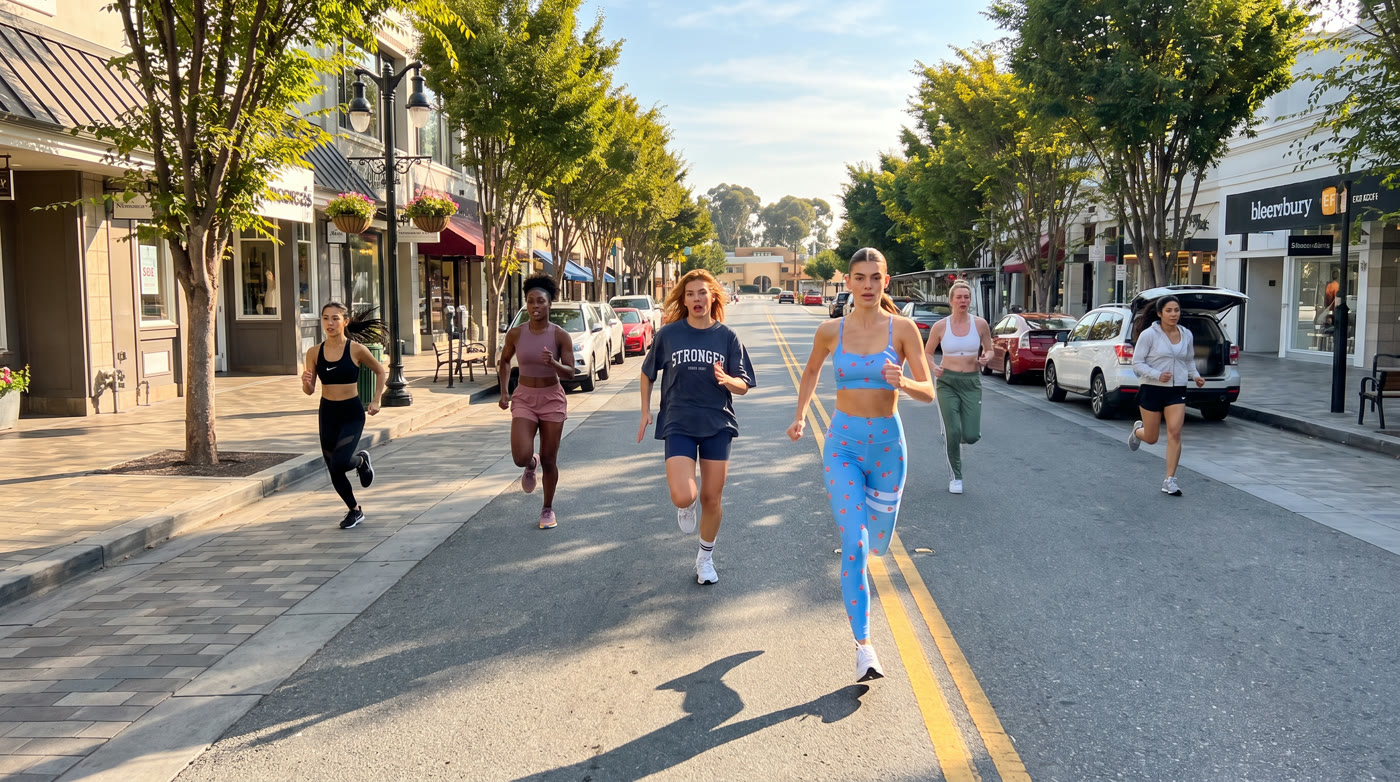
Начальный кадр: шесть женщин бегут по залитой солнцем торговой улице

Широкая улица, закатное солнце и чистый путь для стаи. Лица и одежда взяты из отдельного листа.

Выход · 5 с

Seedance 2.5

Камера смещается к лидерам, и это усиливает эффект. Это все еще черновик в 480p.

Пример 2: первый и последний кадры для точного тайминга

Если вам нужно, чтобы кадр соответствовал определенной композиции, предоставьте модели оба ключевых кадра. Wan 3.0 на базе Higgsfield взяла два изображения и создала 3 секунд видео в разрешении 1080 × 1920 при 30 fps со звуком за 10.5 кредитов. Промпт описывает только то, что происходит между ними. Модель соблюла оба кадра, и трейдер так и не поднял взгляд, как и требовалось в промпте.

Ввод

Первый кадр
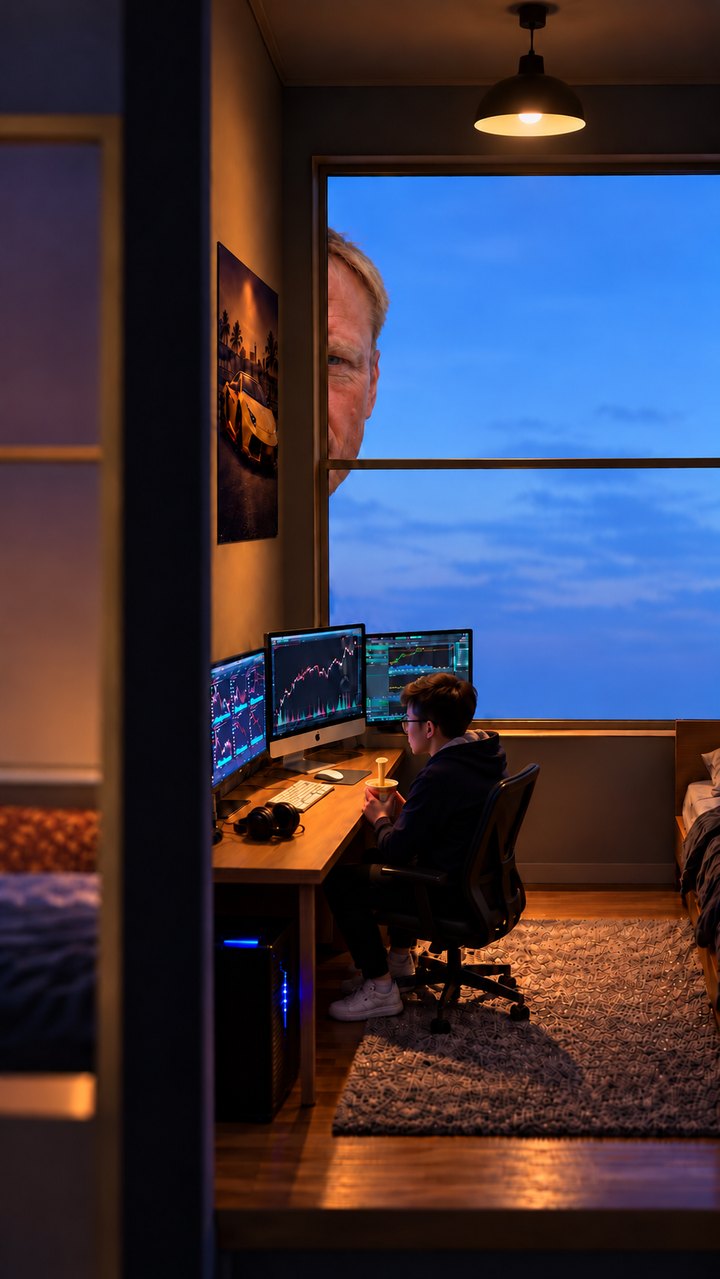
Миниатюрный трейдер за столом, а в окне виден край гигантского лица

Последний кадр - та же комната, но лицо полностью занимает окно.

Результат · 3 с

Wan 3.0

Трейдер продолжает есть; гигант вплывает в кадр и замирает на финальном плане.

Пример 3: говорящее портретное фото

Для использования фото реального человека с реальным голосом прямым путем будет модель аватара. Kling AI Avatar v2 Pro потребовала одно фото и 5.55 секунд записанной речи, это стоило $0.83 на fal и заняло 7 минут. Она сохранила веснушки и текстуру кожи, а каждый жест был создан искусственно, поэтому используйте это для новых обращений в камеру. Чтобы сохранить реальную записанную игру, видеомонтаж работает лучше. Анимируйте реальных людей только с их согласия.

Ввод

Исходное фото
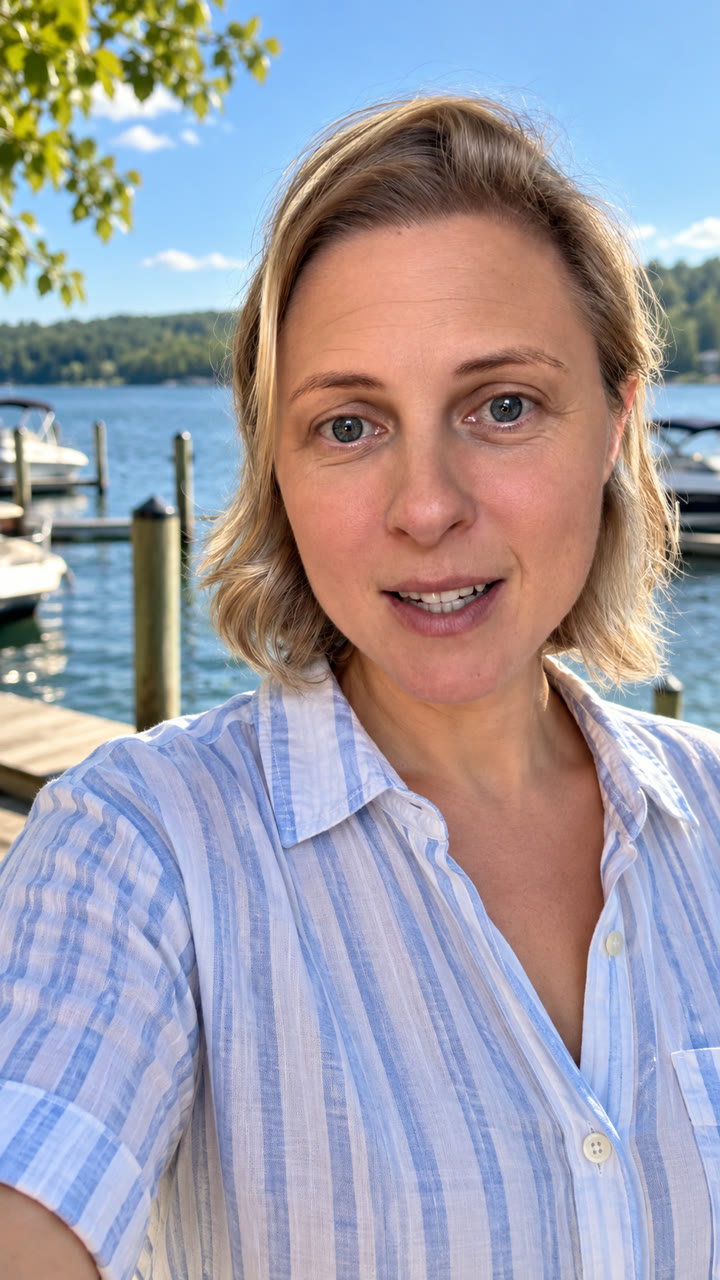
Портретное фото спикера в марине у озера

Одно фото плюс собственная запись диктора.

Выход · 5.55 с

Kling AI Avatar v2 Pro

Близко к фото, с реалистичным эффектом съемки с рук. Здесь ролик воспроизводится без звука.

Как анимировать фото, пошаговая инструкция

  1. Сначала исправьте изображение. Редактируйте его, пока не добьетесь нужного результата. Редактирование одного изображения в Nano Banana Pro при 1K стоит около $0.15, в отличие от стоимости видео.
  2. Соответствуйте выходному формату. Используйте то же соотношение сторон, что и у вашего видео, иначе модель может его обрезать. Наша настройка MiniMax H3 незаметно переключилась на меньший холст, когда соотношение сторон кадра не совпало точно.
  3. Описывайте движение, а не картинку. «Она отрывается от телефона и улыбается. Камера медленно наезжает». В нескольких словах укажите, что остается неизменным.
  4. Запрашивайте одно движение в несколько секунд. Короткие кадры допускают лишь одно небольшое движение.
  5. Проведите дешевый тест. Сделайте черновик в 480p или 720p. Используйте тот же режим модели, который планируете использовать для финального результата.
  6. Проверяйте в полном размере. Осмотрите лица, руки, текст и то, насколько человек остается похожим на себя, прежде чем платить за 1080p.

Какую модель image-to-video вам следует использовать?

По результатам наших собственных запусков. Цены указаны по прайс-листу за 5 секунд, зафиксированы 2 ноября 2026.
НужноМодель720p1080pЧто мы увидели
Самая низкая ценаWan 3.0, API$0.50$1.00Хорошо соблюдены первый и последний кадры; их нельзя смешивать с референсными изображениями в Higgsfield
Один непрерывный кадр с действиемSeedance 2.5, BytePlus≈ $1.16≈ $2.84Наиболее выраженное направление движения; длинные списки исключений (negative prompts) перевели видео в замедленную съемку
Несколько источниковKling 4.0, API≈ $0.79≈ $1.18Использует референсные изображения и всегда добавляет звук

Бесплатные варианты создания видео из изображений

Поиск бесплатного генератора из изображения в видео вполне логичен для первой попытки. Adobe Firefly предлагает бесплатные ежедневные генерации, а Canva позволяет использовать функцию Image to Video, пока не исчерпан ваш ежемесячный лимит ИИ. Мы использовали для тестов ежедневные кредиты Google Flow. Полная таблица бесплатного плана содержит информацию о водяных знаках и ограничениях. Будьте готовы платить, когда вам понадобятся 1080p, отсутствие водяных знаков или коммерческие права.

Для создания нескольких кадров с одним и тем же человеком следуйте руководству по стабильности контента.

Изучите это на собственных кадрах

На воркшопах вы пройдете путь от одного изображения до готового видео за три часа, используя собственный материал.

Найти ваш воркшоп ↗

Дубль 06 · Dreamina Seedance 2.5

Промпт, использованный для этого дубля

runnig6_street_race_16x9_v3 is the first frame of the video: the street, camera position, sunlight and the position of every runner at 0.0s.

six_women_sheet_2 is the identity and wardrobe reference only: the faces, hair, bodies, outfits and shoes of the same six women, top row left to right: 1 the brunette with a slicked-back ponytail in the light blue strawberry-print STRONGER sports bra and leggings, 2 the copper-haired woman in the washed navy oversized STRONGER t-shirt and bike shorts, 3 the woman in black Nike, 4 the ash-blonde in the white adidas top and sage green track pants, 5 the woman in the mauve HOKA top and pink shorts, 6 the woman in the open grey New Balance jacket. Take only the people from six_women_sheet_2; its grey backdrop, flat studio light and side-by-side lineup stay out of the video. Every woman keeps her exact face and outfit from six_women_sheet_2 throughout, with a stable, recognisable face. 16:9.

Side-tracking shot down a shopping street. Light, exactly as in runnig6_street_race_16x9_v3: the only light is the late-afternoon sun, low in the sky at the far end of the street and slightly to the right, about 15 degrees above the horizon behind the runners. It is hard, direct sunlight with crisp shadows, warm golden in colour, while the shade stays cool and slightly blue. It rims the runners' hair, shoulders, arms and calves with a bright warm edge that separates them from the street, and throws long hard shadows from their feet toward the camera and slightly left. The fronts of their bodies and their faces are on the shadow side, one to two stops darker, lit only by soft warm bounce from the pale asphalt, with natural skin micro-texture and subtle pores. When the camera reaches their side, the same sun comes from the right edge of the frame, behind them: the backs of their heads, shoulders and calves glow, their faces turned toward the left of the frame stay in soft bounce light, and their shadows stretch ahead of them across the asphalt. Fine dust kicked up by their shoes catches the backlight. The sun does not move and the exposure does not change during the camera move; only the dappled shadows of the street trees slide over the runners as they pass under them.

The video starts exactly on @Image1: six women racing hard straight toward the camera down the middle of the street. Over the first 1.5 seconds the camera swings from this front view around to the right side of the frame, the runners' left side, dropping to chest height and moving in close, then travels parallel with them for the rest of the shot, moving with the group but slightly slower so they pull forward through the frame. They cover about twenty-five metres of the street, so the background travels more than two full frame widths: the storefronts, lamp posts with hanging flower baskets and parked cars from the opening frame leave the edge within two seconds, and three or four shopfronts, street trees and parked cars that were never in the opening frame sweep in and pass behind them.

Breathing and faces: every runner breathes in a real running rhythm synced to her stride, a quick inhale with lips nearly closed, then a hard exhale through an open mouth, every second step, so mouths keep opening and closing instead of staying open. Their expressions change as the race tightens: eyebrows pull together, jaws clench, lips press into a line before a push, cheeks puff on a sharp exhale, eyes flick sideways at the rival next to them.

[0:00-1:50] The pack runs toward the camera as in runnig6_street_race_16x9_v3, backlit, while the camera swings to their side. The lead in the strawberry-print STRONGER set breathes steadily, face focused, lips closing between exhales.
[1:50-2:50] The camera is beside them; the lead runs closest, filling half the frame height, the sun rimming the back of her ponytail and shoulders. The copper-haired runner in the navy STRONGER t-shirt glances at her, presses her lips together, then surges up to her shoulder with a sharp exhale through gritted teeth.
[2:50-3:50] They pass under a street tree and leaf shadows slide across their faces and arms, then warm sun hits their backs again. The lead feels the rival there: her brow tightens, her jaw sets, and she drives her arms harder with a short, strong exhale. Behind them the runner in the mauve HOKA top and the blonde in green track pants push hard, faces straining, mouths opening wide on each breath.
[3:50-5:00] The two STRONGER runners are level, stride for stride, passing a new corner shopfront; both faces show the last extra effort, eyes narrowed, nostrils flaring on the inhale, mouths snapping open on each exhale. Full racing speed, fast leg cadence, arms driving hard, ponytails and hair whipping backward and glowing in the backlight, faces sharp, clothing and printed logos readable, heavy speed blur across the buildings, parked cars and pavement while the runners stay sharp.

Wan 3.0 · план А · от начального до среднего кадра, 3 с

Промпт, использованный для кадра A

3-second contemporary digital comedy shot inside a physical miniature dollhouse. One continuous take: a miniature trader eats noodles at his desk while a giant, unnoticed, slowly rises into view behind his rear window.

FORMAT: 9:16, 3.0 seconds, photoreal digital cinema with native sound.

START AND END: open exactly on the supplied start frame (trader room; trader holding his noodle cup near his mouth; only a sliver of the giant observer's face visible at the far left edge of the rear window) and end exactly on the supplied end frame (same room; the observer's whole face filling the rear window, looking down at the trader). Keep both frames' composition, proportions, floor height, window geometry, furniture, desk items and lighting.

TRADER: miniature young man at the desk, glasses, black hoodie, dark trousers, white trainers. He eats continuously for the whole shot: cup held near his mouth in one hand, lifting forkfuls of noodles, chewing, eyes on his three monitors. He never notices the observer, never turns, never speaks. Black over-ear headphones lie untouched on the desk beside the keyboard.
OBSERVER: giant blond man, blue eyes, light-blue T-shirt, outside the rear window; exactly the man in the end frame. He moves from almost out of view at the left edge across and into the window, curious, settling into the end frame's head position, angle and downward gaze. Lips closed, silent, hands below the sill.

STYLE: frame-matched lens perspective, deep focus holding trader and observer together, restrained acting, natural skin and cloth. A photographed miniature set with a real person outside, not generated footage.
COLOR: warm brown and charcoal room under a warm pendant; blue daylight outside the window.
ENVIRONMENT: the trader room only: desk with three monitors, keyboard, headphones, bed, rug, wall artwork. Architecture and furniture stay fixed.

CAMERA: very slight physical dolly to camera-right along the open dollhouse front, matching the small shift between the start and end frames; constant height, direction and focal length. No zoom.

[0.0s-2.5s] The trader keeps eating - forkfuls lifted and chewed, eyes on the monitors. The observer glides in from the left edge of the rear window, his face rising and sliding across until it fills the window, quietly watching the trader eat. SFX: faint computer hum, fork against the cup, soft slurping, chewing.

[2.5s-3.0s] Held composition matching the end frame: the observer's face filling the rear window, eyes on the trader; the trader still eating, unaware. Camera settled.

AUDIO: eating sounds and computer hum only; subtle room ambience. No dialogue, no music, no narration, no on-screen text, no subtitles, no logo.

CONSTRAINTS: one unbroken take; no cuts, dissolves, black frames or zoom. Nobody speaks. The trader keeps eating and never looks at the window. The headphones stay on the desk. Preserve identities, wardrobe, miniature-to-giant scale, room dimensions, window geometry and desk items. Stable faces throughout, no morphing, no deformation, photoreal cinematic finish.

Аватары 1 и 2 · OmniHuman 1.5 и Kling AI Avatar v2 Pro

Промпт, использованный для обоих аватаров

A woman talks directly to the camera in a handheld selfie video on a sunny lakeside marina. Natural, relaxed delivery: small head nods and tilts, lively eyebrows, natural blinks, subtle shoulder movement, slight handheld camera sway as if she holds the phone at arm's length. Her hair moves lightly in the breeze; boats rock gently on the water behind her. Her face, hair and striped shirt stay exactly as in the photo. Realistic skin, natural daylight.

Inputs: the marina photo as the image, the speaker's own recording (0-5.55 s) as the audio. OmniHuman 1.5 at 720p.