Що робить анімацію зображення якісною

Моделі продовжують те, що бачать, включаючи наявні проблеми. У наших шести дублях для рекламного ролика переповнений, помітно синтетичний початковий кадр залишався сумнівним, яким би хорошим не був промпт, тоді як ширший і більш реалістичний кадр дав тій самій моделі матеріал для роботи. Перед генерацією перевірте своє зображення на наявність таких ознак:

  • Простір для руху. Об'єкт, притиснутий до краю кадру, не має куди рухатися. Залишайте простір у напрямку руху.
  • Обличчя з достатньою кількістю пікселів. Маленькі обличчя перемальовуються погано. Генеруйте ширший кадр, а потім обрізайте, або використовуйте ближче фото.
  • Реалістичне світло. Одне чітке джерело світла краще зберігається під час руху, ніж плоске або змішане світло.
  • Жодних зайвих деталей, які ви не хочете анімувати. Усе в кадрі може рухатися, танути або множитися.

Приклад 1: перетворення згенерованого стоп-кадру на кадр із перегонів

Один і той самий початковий кадр та картка ідентичності були використані для кількох моделей. Ось обраний дубль: Seedance 2.5 у Dreamina, 5 секунд при 480p. Це була чернетка, і завдяки часовим вказівкам бічний рух камери, напруга обличчя та відчуття суперництва були передані чітко.

Вхідні дані

Початковий кадр
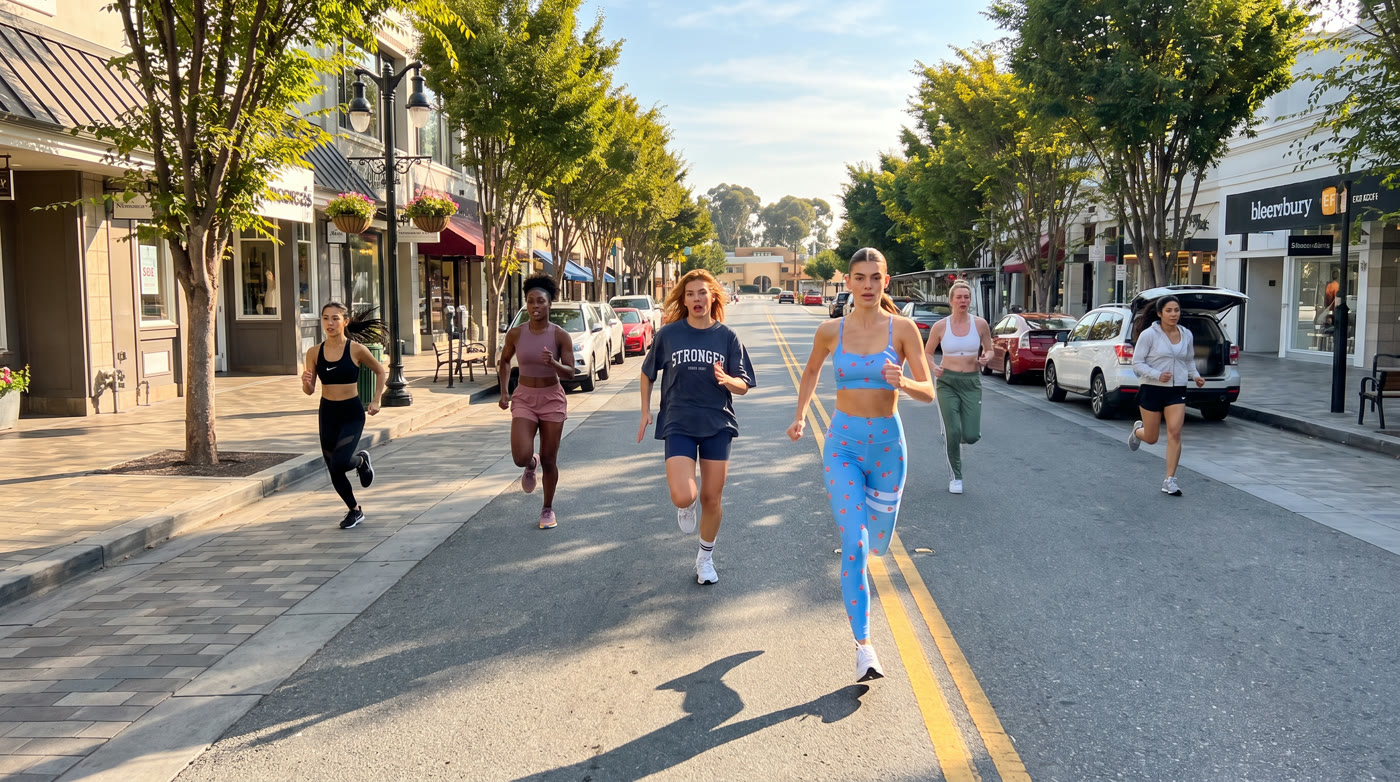
Початковий кадр із шістьма жінками, що біжать сонячною торговою вулицею

Широка вулиця, вечірнє сонце та чистий шлях для зграї. Обличчя та вбрання були взяті з окремого аркуша.

Результат · 5 с

Seedance 2.5

Камера зміщується збоку від лідерів, і зусилля стає помітним. Це все ще чернетка 480p.

Приклад 2: перший і останній кадри для точного таймінгу

Якщо ви хочете, щоб кадр відповідав певній композиції, надайте моделі обидва кінцеві стани. Wan 3.0 на Higgsfield взяв два зображення та створив 3 секунд відео у роздільній здатності 1080 × 1920 та 30 fps зі звуком за 10.5 кредитів. Промпт описує лише те, що відбувається між ними. Модель дотрималася обох кадрів, і трейдер так і не піднімає погляду, як і вимагав промпт.

Вхідні дані

Перший кадр
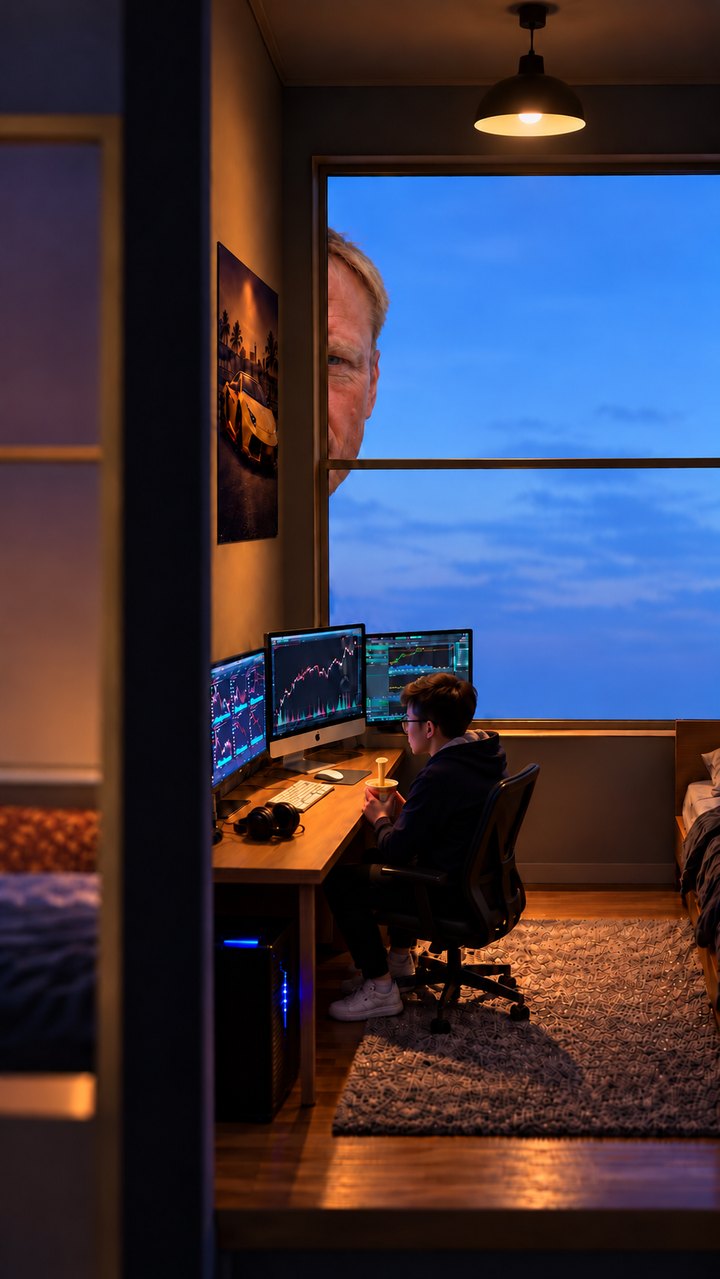
Мініатюрний трейдер за столом, а біля вікна видно край обличчя велетня

Останній кадр - це та сама кімната, де все обличчя займає весь план.

Результат · 3 с

Wan 3.0

Трейдер продовжує їсти; велетень з'являється і зупиняється на фінальному кадрі.

Приклад 3: портретне фото, що говорить

Для фото реальної людини з реальним голосом прямим шляхом є модель аватара. Kling AI Avatar v2 Pro потребувала лише одне фото та 5.55 секунд записаної мови, що коштувало $0.83 на fal і зайняло 7 хвилин. Вона зберегла веснянки та текстуру шкіри, а кожен жест є вигаданим, тому використовуйте це для нових звернень до камери. Щоб зберегти реальне записане виконання, редагування відео працює краще. Анімуйте реальних людей лише за їхньою згодою.

Вхідні дані

Вихідне фото
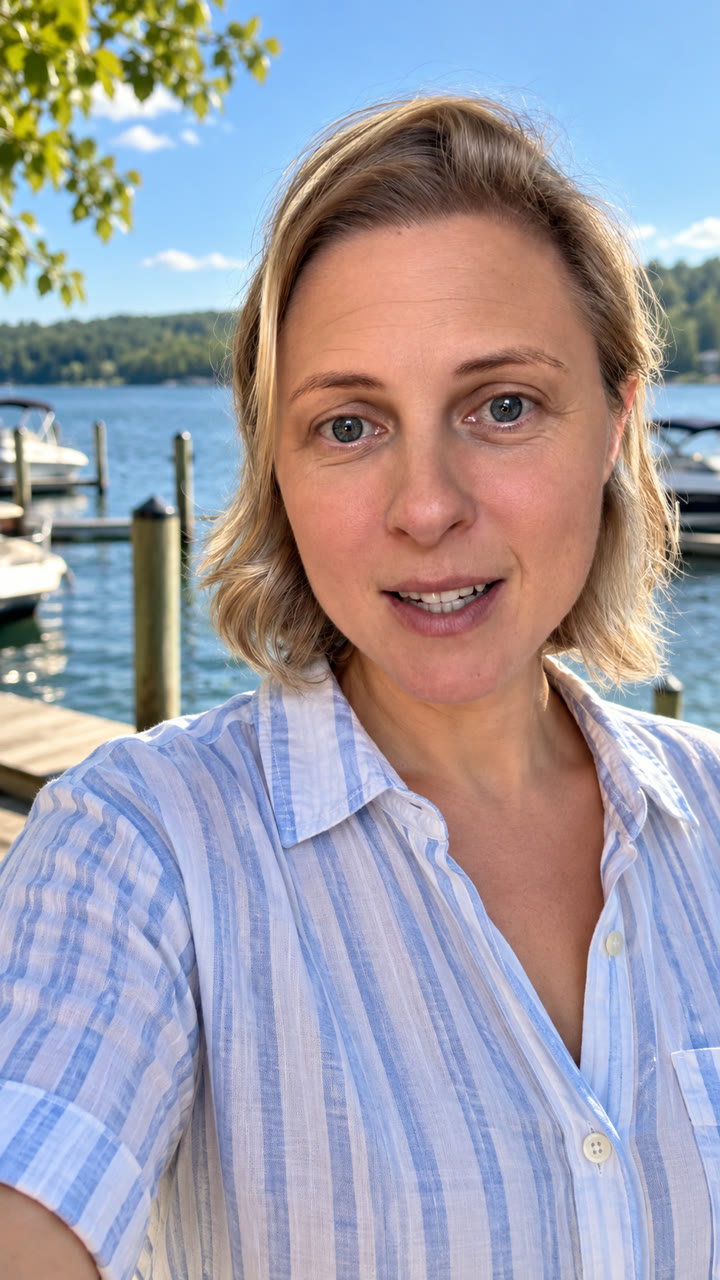
Портретне фото спікера на марині біля озера

Одна фотографія плюс власна аудіозапис спікера.

Результат · 5.55 с

Kling AI Avatar v2 Pro

Близко до фото, з реалістичним ефектом тремтіння камери з рук. Тут кліп відтворюється без звуку.

Як анімувати фото, покрокова інструкція

  1. Спочатку виправте зображення. Редагуйте його, доки воно не стане ідеальним. Редагування одного зображення коштує близько $0.15 на Nano Banana Pro при 1K, тоді як відео розраховується в доларах.
  2. Відповідність формату виводу. Використовуйте те саме співвідношення сторін, що й у відео, яке ви хочете отримати, інакше модель може його обрізати. Наш MiniMax H3 налаштування непомітно перейшло на менший полотно, коли співвідношення сторін кадру не збігалося точно.
  3. Описуйте рух, а не картинку. «Вона відриває погляд від телефону і посміхається. Камера повільно наїжджає». Коротко опишіть те, що залишається незмінним.
  4. Запитуйте на один рух кожні кілька секунд. Короткі кадри дозволяють лише один невеликий рух.
  5. Проведіть дешевий тест. Чернетка у 480p або 720p. Використовуйте той самий режим моделі, який будете використовувати для фінального результату.
  6. Перевіряйте у повному розмірі. Звертайте увагу на обличчя, руки, текст і на те, чи людина все ще схожа на себе, перш ніж платити за 1080p.

Яку модель image-to-video варто використовувати?

З наших власних запусків. Ціни вказані за 5 секунд станом на 2 листопада 2026.
ПотрібноМодель720p1080pТе, що ми побачили
Найнижча цінаWan 3.0, API$0.50$1.00Добре дотримується першого та останнього кадрів; неможливо змішувати їх із референтними зображеннями на Higgsfield
Один безперервний кадр з дієюSeedance 2.5, BytePlus≈ $1.16≈ $2.84Найкраща режисура перегонів; довгі списки негативних промптів перевели відео в уповільнену зйомку
Кілька джерелKling 4.0, API≈ $0.79≈ $1.18Використовує референтні зображення та завжди додає звук

Безкоштовні варіанти створення відео з зображень

Пошук безкоштовного генератора image-to-video є логічним для першої спроби. Adobe Firefly пропонує безкоштовні щоденні генерації, а Canva дозволяє створювати відео з фото, поки діє ваш щомісячний ліміт ШІ. Щоденні кредити Google Flow - це те, що ми використовували для тестів. Повна таблиця безкоштовного плану показує водяні знаки та обмеження. Будьте готові платити, коли вам знадобиться 1080p, відсутність водяних знаків або комерційні права.

Для кількох кадрів з однією і тією ж людиною продовжуйте читати the consistency guide.

Вивчіть це на власних кадрах

На воркшопах ви пройдете шлях від одного зображення до готового відео за три години, використовуючи власний матеріал.

Знайти ваш воркшоп ↗

Дубль 06 · Dreamina Seedance 2.5

Промпт, використаний для цього дубля

runnig6_street_race_16x9_v3 is the first frame of the video: the street, camera position, sunlight and the position of every runner at 0.0s.

six_women_sheet_2 is the identity and wardrobe reference only: the faces, hair, bodies, outfits and shoes of the same six women, top row left to right: 1 the brunette with a slicked-back ponytail in the light blue strawberry-print STRONGER sports bra and leggings, 2 the copper-haired woman in the washed navy oversized STRONGER t-shirt and bike shorts, 3 the woman in black Nike, 4 the ash-blonde in the white adidas top and sage green track pants, 5 the woman in the mauve HOKA top and pink shorts, 6 the woman in the open grey New Balance jacket. Take only the people from six_women_sheet_2; its grey backdrop, flat studio light and side-by-side lineup stay out of the video. Every woman keeps her exact face and outfit from six_women_sheet_2 throughout, with a stable, recognisable face. 16:9.

Side-tracking shot down a shopping street. Light, exactly as in runnig6_street_race_16x9_v3: the only light is the late-afternoon sun, low in the sky at the far end of the street and slightly to the right, about 15 degrees above the horizon behind the runners. It is hard, direct sunlight with crisp shadows, warm golden in colour, while the shade stays cool and slightly blue. It rims the runners' hair, shoulders, arms and calves with a bright warm edge that separates them from the street, and throws long hard shadows from their feet toward the camera and slightly left. The fronts of their bodies and their faces are on the shadow side, one to two stops darker, lit only by soft warm bounce from the pale asphalt, with natural skin micro-texture and subtle pores. When the camera reaches their side, the same sun comes from the right edge of the frame, behind them: the backs of their heads, shoulders and calves glow, their faces turned toward the left of the frame stay in soft bounce light, and their shadows stretch ahead of them across the asphalt. Fine dust kicked up by their shoes catches the backlight. The sun does not move and the exposure does not change during the camera move; only the dappled shadows of the street trees slide over the runners as they pass under them.

The video starts exactly on @Image1: six women racing hard straight toward the camera down the middle of the street. Over the first 1.5 seconds the camera swings from this front view around to the right side of the frame, the runners' left side, dropping to chest height and moving in close, then travels parallel with them for the rest of the shot, moving with the group but slightly slower so they pull forward through the frame. They cover about twenty-five metres of the street, so the background travels more than two full frame widths: the storefronts, lamp posts with hanging flower baskets and parked cars from the opening frame leave the edge within two seconds, and three or four shopfronts, street trees and parked cars that were never in the opening frame sweep in and pass behind them.

Breathing and faces: every runner breathes in a real running rhythm synced to her stride, a quick inhale with lips nearly closed, then a hard exhale through an open mouth, every second step, so mouths keep opening and closing instead of staying open. Their expressions change as the race tightens: eyebrows pull together, jaws clench, lips press into a line before a push, cheeks puff on a sharp exhale, eyes flick sideways at the rival next to them.

[0:00-1:50] The pack runs toward the camera as in runnig6_street_race_16x9_v3, backlit, while the camera swings to their side. The lead in the strawberry-print STRONGER set breathes steadily, face focused, lips closing between exhales.
[1:50-2:50] The camera is beside them; the lead runs closest, filling half the frame height, the sun rimming the back of her ponytail and shoulders. The copper-haired runner in the navy STRONGER t-shirt glances at her, presses her lips together, then surges up to her shoulder with a sharp exhale through gritted teeth.
[2:50-3:50] They pass under a street tree and leaf shadows slide across their faces and arms, then warm sun hits their backs again. The lead feels the rival there: her brow tightens, her jaw sets, and she drives her arms harder with a short, strong exhale. Behind them the runner in the mauve HOKA top and the blonde in green track pants push hard, faces straining, mouths opening wide on each breath.
[3:50-5:00] The two STRONGER runners are level, stride for stride, passing a new corner shopfront; both faces show the last extra effort, eyes narrowed, nostrils flaring on the inhale, mouths snapping open on each exhale. Full racing speed, fast leg cadence, arms driving hard, ponytails and hair whipping backward and glowing in the backlight, faces sharp, clothing and printed logos readable, heavy speed blur across the buildings, parked cars and pavement while the runners stay sharp.

Wan 3.0 · план А · від початкового до середнього кадру, 3 с

Промпт, використаний для кадру A

3-second contemporary digital comedy shot inside a physical miniature dollhouse. One continuous take: a miniature trader eats noodles at his desk while a giant, unnoticed, slowly rises into view behind his rear window.

FORMAT: 9:16, 3.0 seconds, photoreal digital cinema with native sound.

START AND END: open exactly on the supplied start frame (trader room; trader holding his noodle cup near his mouth; only a sliver of the giant observer's face visible at the far left edge of the rear window) and end exactly on the supplied end frame (same room; the observer's whole face filling the rear window, looking down at the trader). Keep both frames' composition, proportions, floor height, window geometry, furniture, desk items and lighting.

TRADER: miniature young man at the desk, glasses, black hoodie, dark trousers, white trainers. He eats continuously for the whole shot: cup held near his mouth in one hand, lifting forkfuls of noodles, chewing, eyes on his three monitors. He never notices the observer, never turns, never speaks. Black over-ear headphones lie untouched on the desk beside the keyboard.
OBSERVER: giant blond man, blue eyes, light-blue T-shirt, outside the rear window; exactly the man in the end frame. He moves from almost out of view at the left edge across and into the window, curious, settling into the end frame's head position, angle and downward gaze. Lips closed, silent, hands below the sill.

STYLE: frame-matched lens perspective, deep focus holding trader and observer together, restrained acting, natural skin and cloth. A photographed miniature set with a real person outside, not generated footage.
COLOR: warm brown and charcoal room under a warm pendant; blue daylight outside the window.
ENVIRONMENT: the trader room only: desk with three monitors, keyboard, headphones, bed, rug, wall artwork. Architecture and furniture stay fixed.

CAMERA: very slight physical dolly to camera-right along the open dollhouse front, matching the small shift between the start and end frames; constant height, direction and focal length. No zoom.

[0.0s-2.5s] The trader keeps eating - forkfuls lifted and chewed, eyes on the monitors. The observer glides in from the left edge of the rear window, his face rising and sliding across until it fills the window, quietly watching the trader eat. SFX: faint computer hum, fork against the cup, soft slurping, chewing.

[2.5s-3.0s] Held composition matching the end frame: the observer's face filling the rear window, eyes on the trader; the trader still eating, unaware. Camera settled.

AUDIO: eating sounds and computer hum only; subtle room ambience. No dialogue, no music, no narration, no on-screen text, no subtitles, no logo.

CONSTRAINTS: one unbroken take; no cuts, dissolves, black frames or zoom. Nobody speaks. The trader keeps eating and never looks at the window. The headphones stay on the desk. Preserve identities, wardrobe, miniature-to-giant scale, room dimensions, window geometry and desk items. Stable faces throughout, no morphing, no deformation, photoreal cinematic finish.

Аватари 1 та 2 · OmniHuman 1.5 та Kling AI Avatar v2 Pro

Промпт, використаний для обох аватарів

A woman talks directly to the camera in a handheld selfie video on a sunny lakeside marina. Natural, relaxed delivery: small head nods and tilts, lively eyebrows, natural blinks, subtle shoulder movement, slight handheld camera sway as if she holds the phone at arm's length. Her hair moves lightly in the breeze; boats rock gently on the water behind her. Her face, hair and striped shirt stay exactly as in the photo. Realistic skin, natural daylight.

Inputs: the marina photo as the image, the speaker's own recording (0-5.55 s) as the audio. OmniHuman 1.5 at 720p.