El objetivo era un solo plano en una habitación específica de una casa de muñecas fotorrealista, terminando con la cámara desplazándose hacia la siguiente habitación. Dura unos nueve segundos. Un pequeño comerciante come fideos frente a tres monitores. Un hombre gigante, yo, lo observa a través de la ventana trasera. El comerciante espeta: “¡Déjame en paz!” y lanza algo contra el cristal. El gigante dice: “¡Lo siento!”, y la cámara se desliza hacia la sala de yoga contigua, donde una mujer mantiene la vista en su tableta.

El plano corto original parecía sencillo, pero resultó complicado en cada paso de la producción: dos personajes hablando con sincronización labial, un lanzamiento con física real, un movimiento de cámara continuo entre dos habitaciones y un rostro grande que ocupa el encuadre durante segundos. Estos son los resultados, uno al lado del otro, con los prompts.

El plan: primero tres imágenes

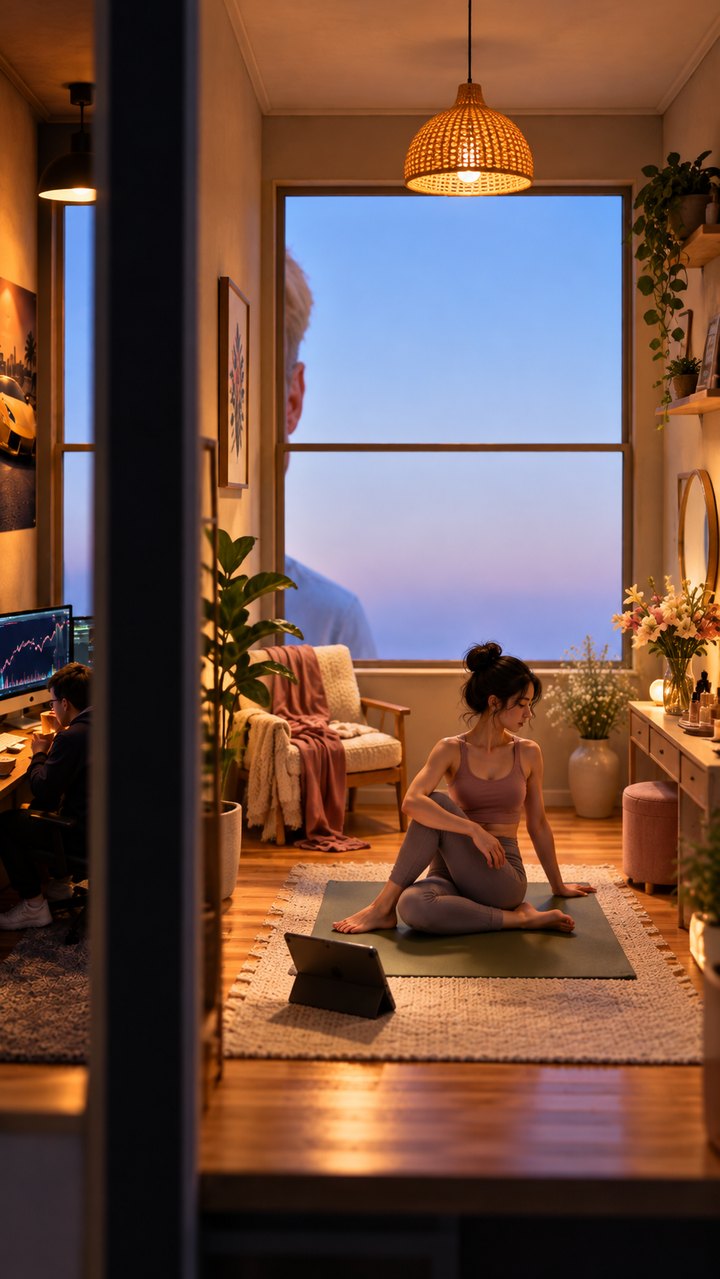
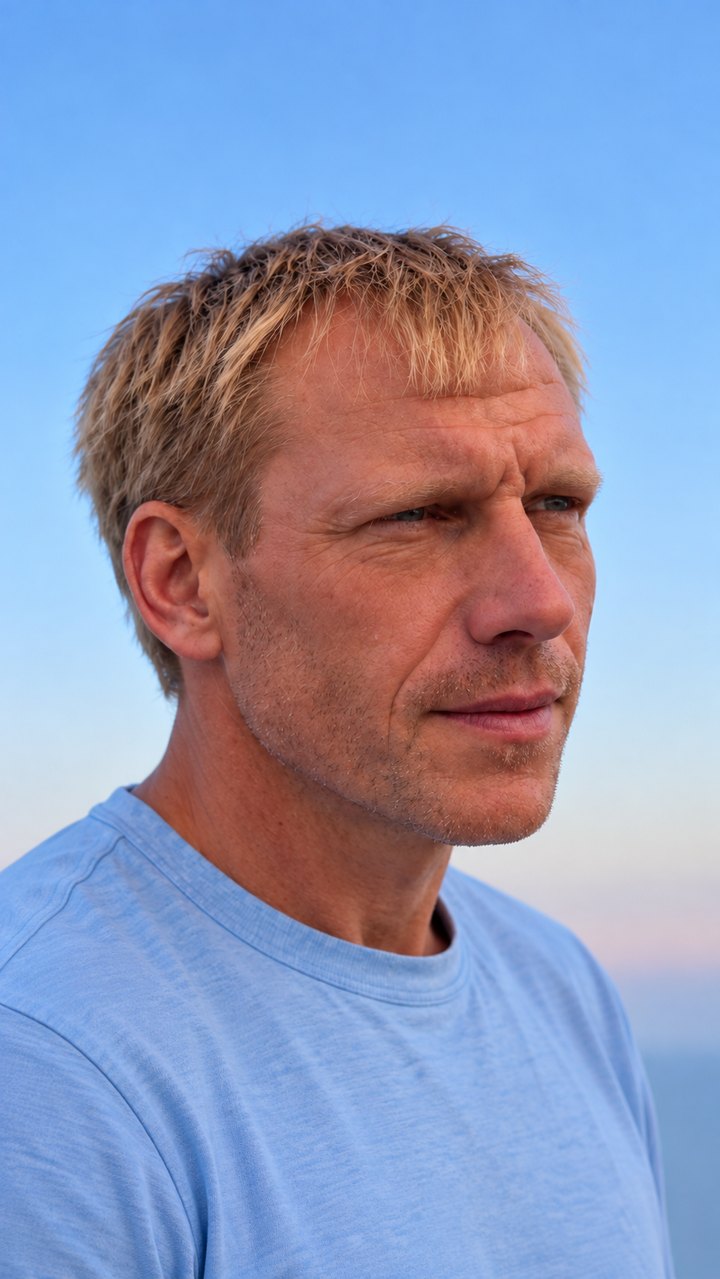
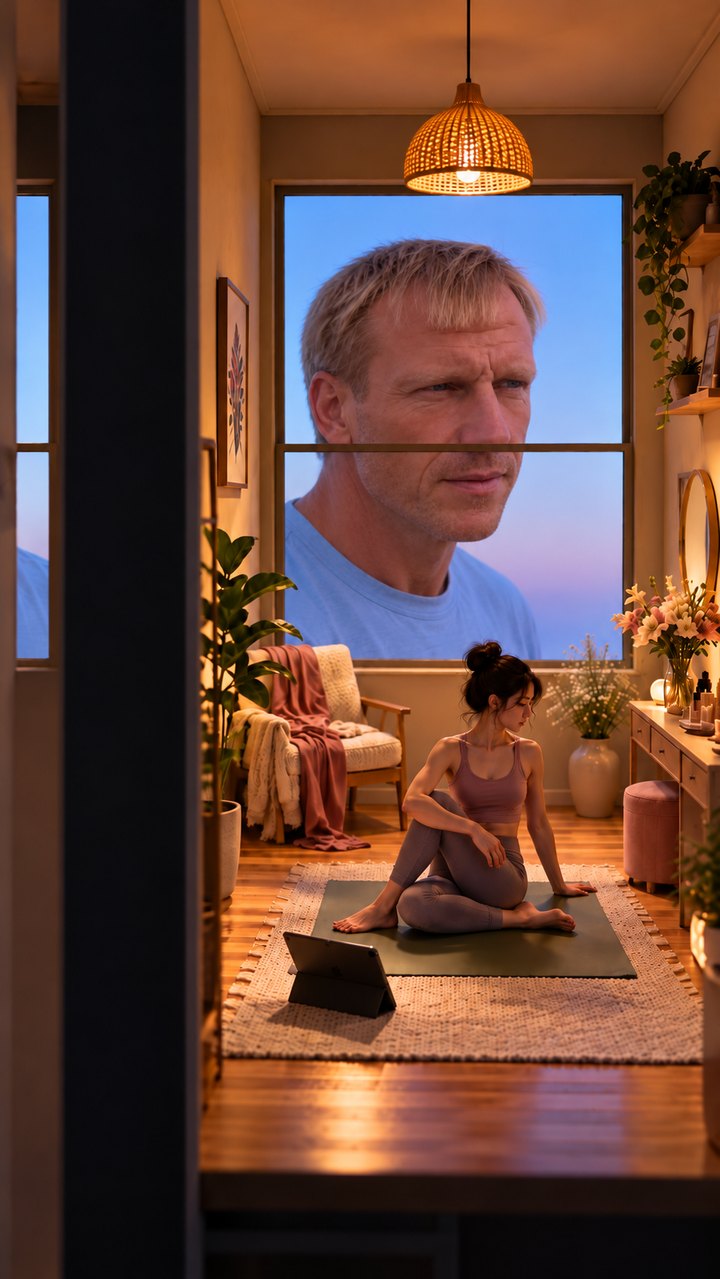
El método consistió en aprobar las imágenes clave antes de generar cualquier vídeo: la apertura de la habitación del trader, el gigante observándolo y el fotograma de cierre en la sala de yoga.

Inicio

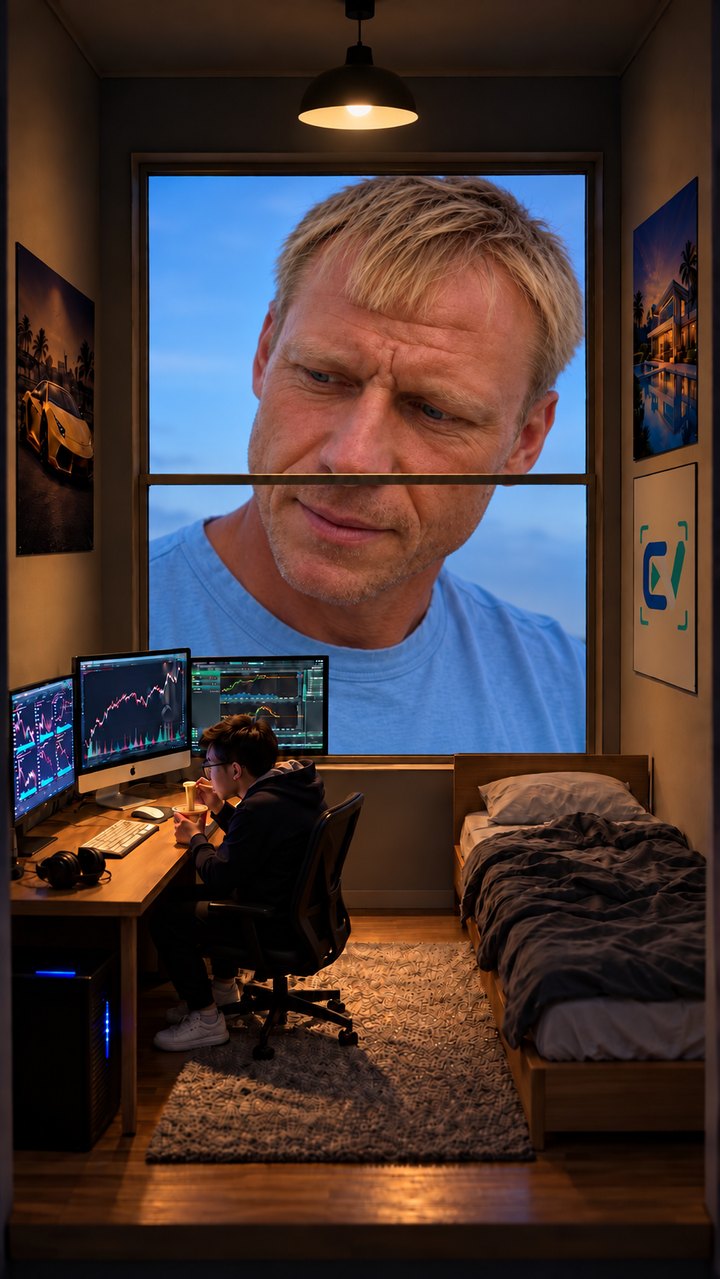
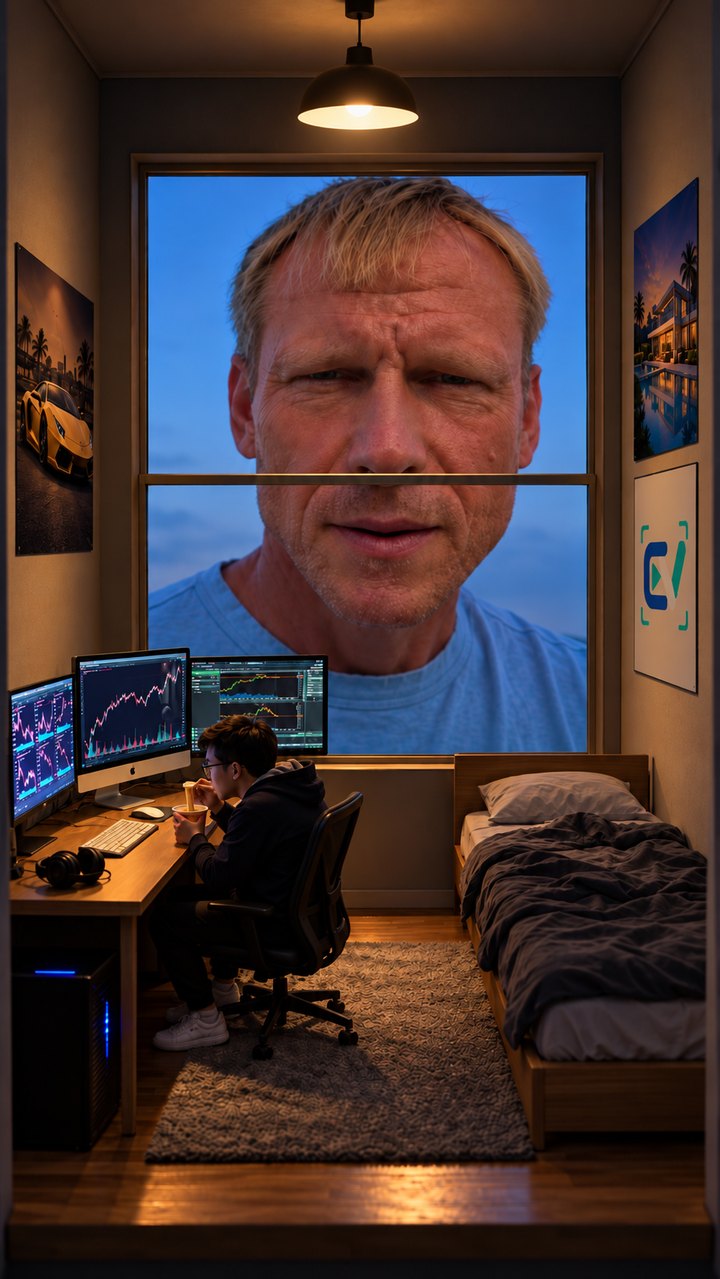
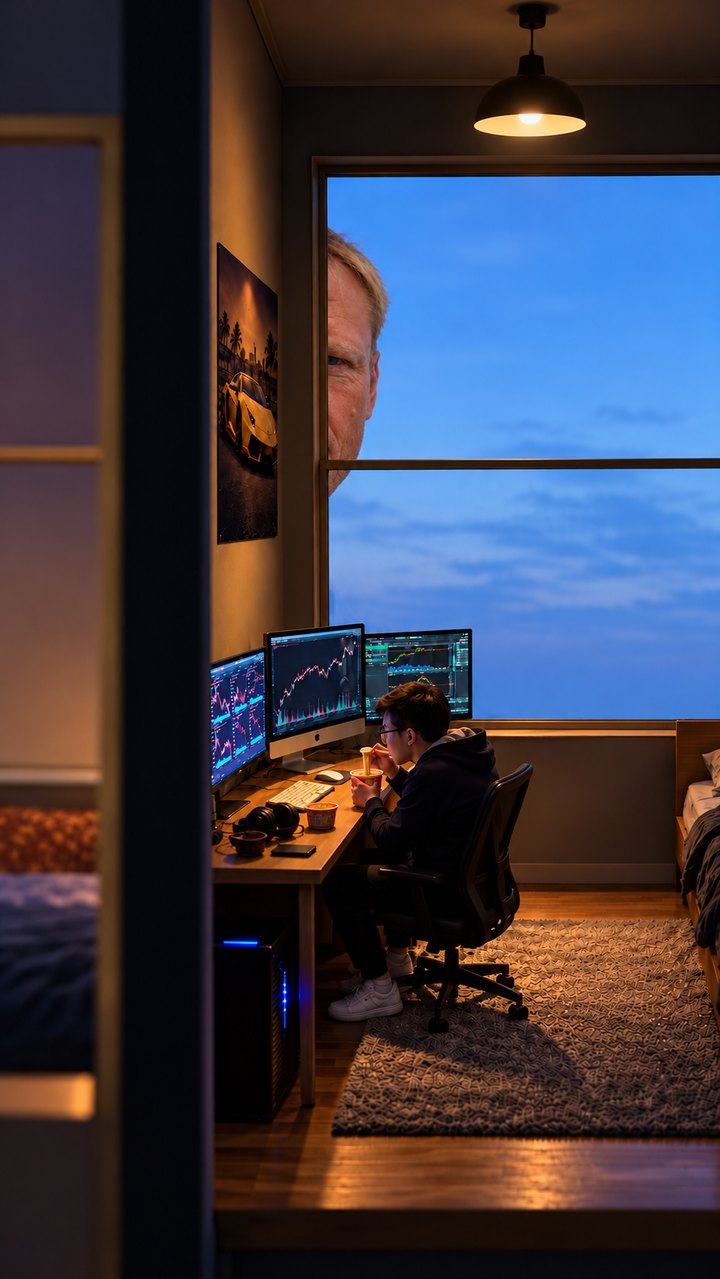
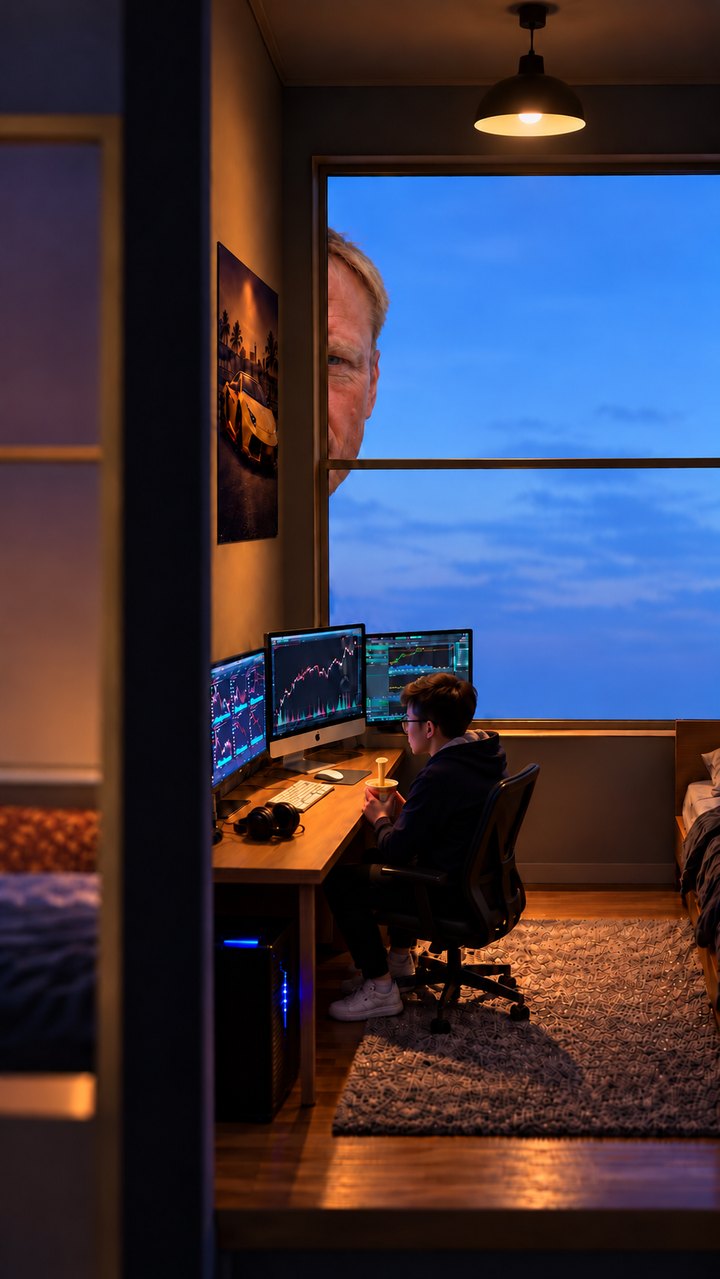
La habitación del trader

El trader en miniatura ante sus tres monitores, sosteniendo un vaso de fideos; un fragmento del rostro del gigante en el borde de la ventana; una pared divisoria oscura a la izquierda.

Un fragmento de la habitación anterior, el muro divisorio y solo el borde del rostro del gigante.

Centro

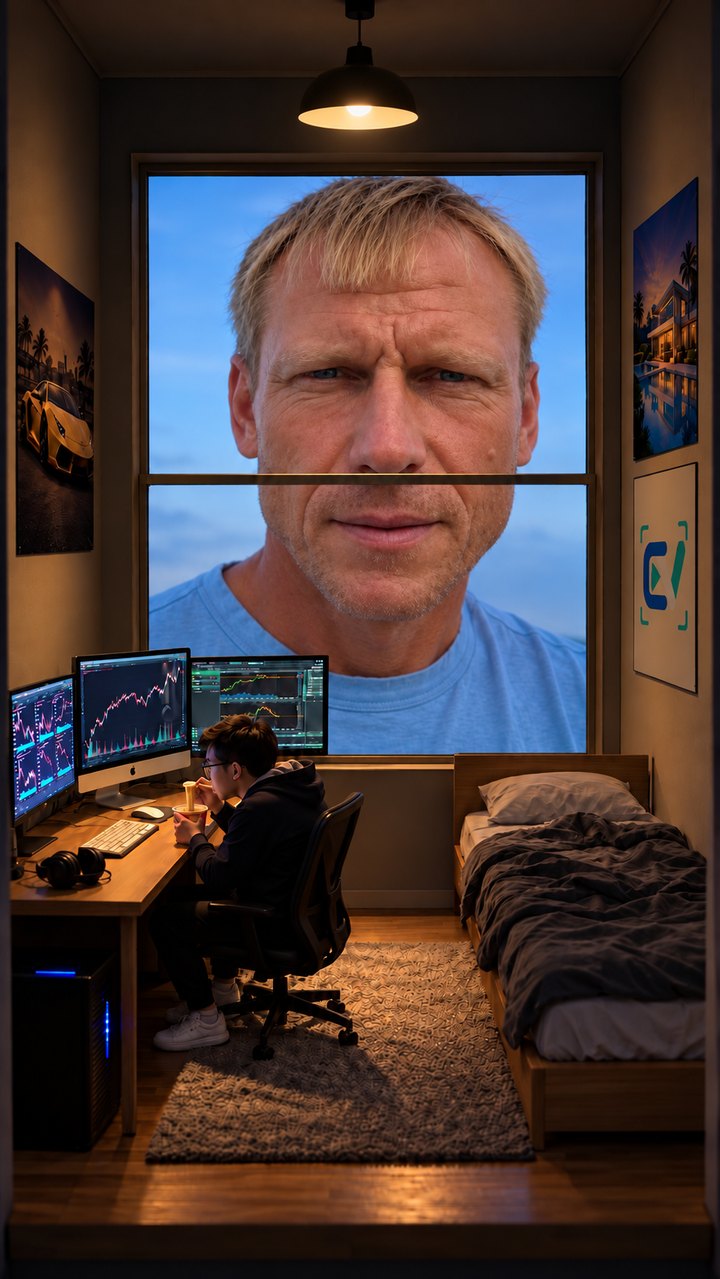
El gigante está observando

El gigante rubio llena la ventana trasera y mira hacia abajo al comerciante.

Su rostro llena la ventana, con los ojos puestos en el operador. Este fotograma se convertirá más tarde en el punto de corte compartido.

Fin

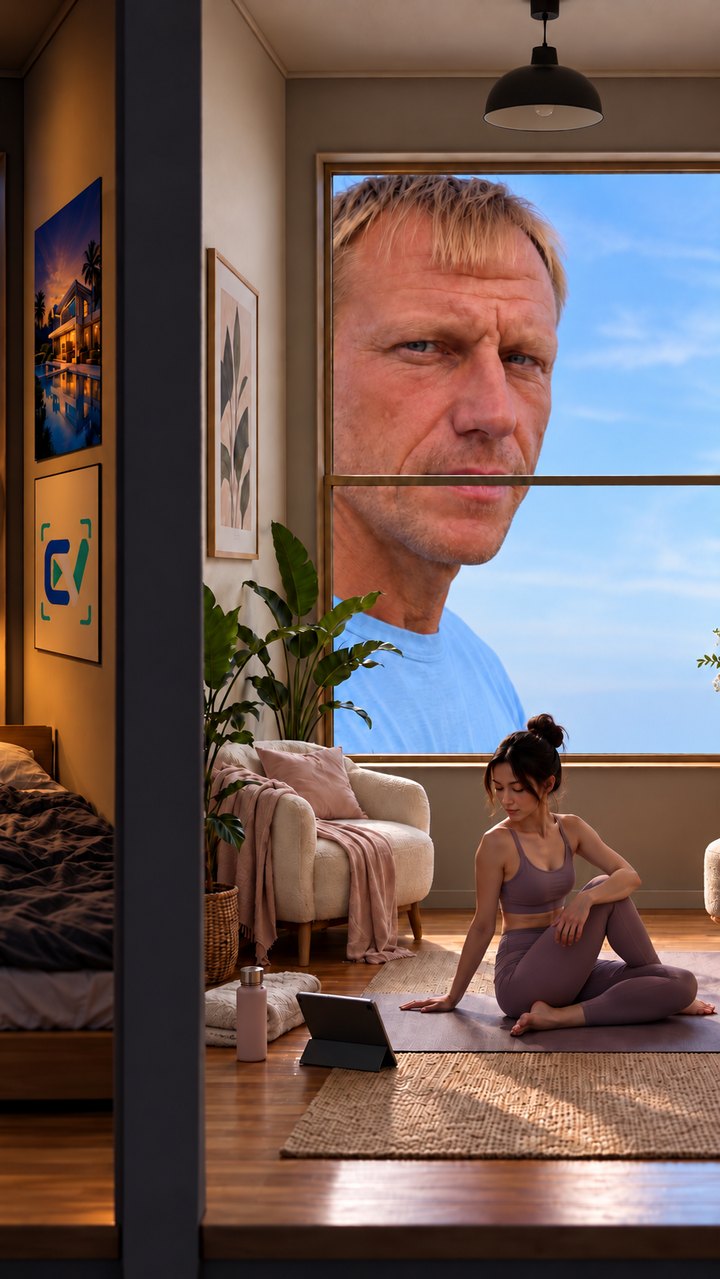
La sala de yoga

La sala de yoga de al lado: una mujer en una esterilla con una tablet, el gigante junto a la ventana, la pared de la sala de trading a la izquierda.

Mismo tamaño de ventana, altura del suelo y escala facial, una sala a la derecha.

Imágenes, ronda 1: 33 imágenes en un chat de ChatGPT

El primer intento fue una conversación ordinaria con ChatGPT en un plan Plus: describir la habitación, adjuntar una foto de mi cara, pedir cambios. Me llevó 26 mensajes y produjo 33 imágenes, y aproximadamente el 18 de mis mensajes fueron correcciones. Cada respuesta reconstruía la escena desde cero, por lo que arreglar una cosa rompía otra.

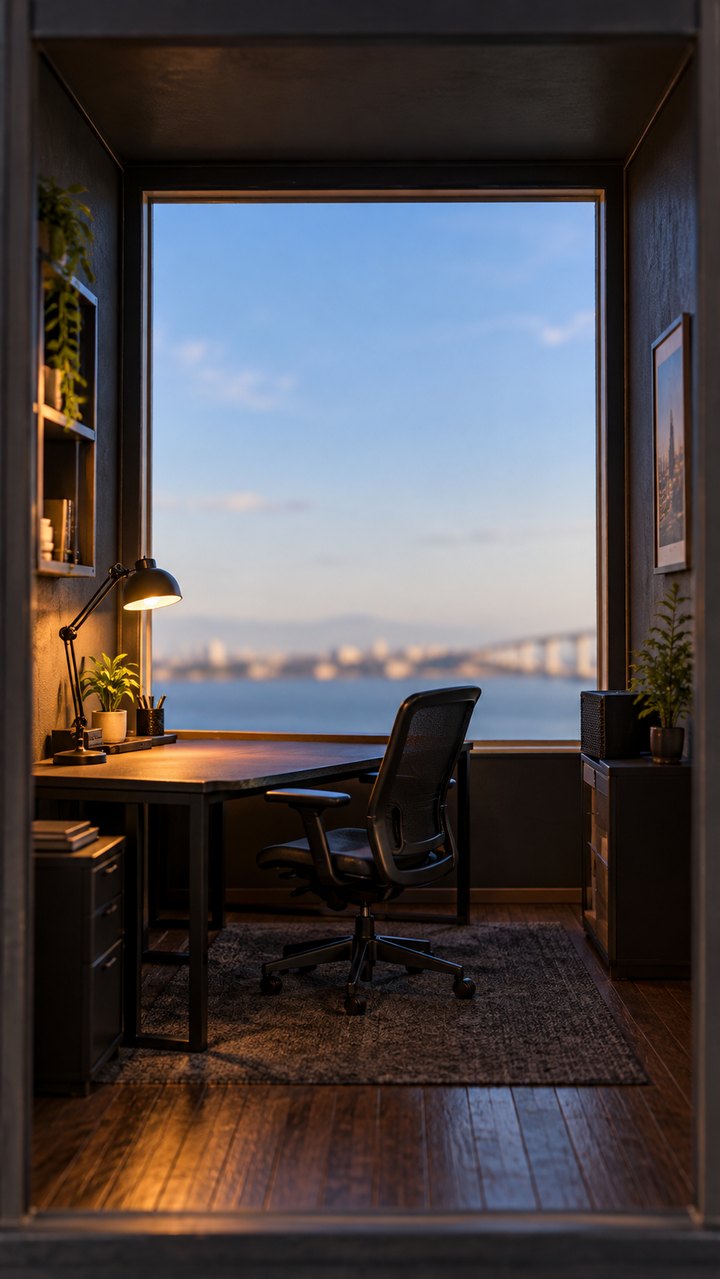
Una habitación vacía con una ventana y un escritorio, sin monitores y sin personas.
Sin monitores, sin operador.
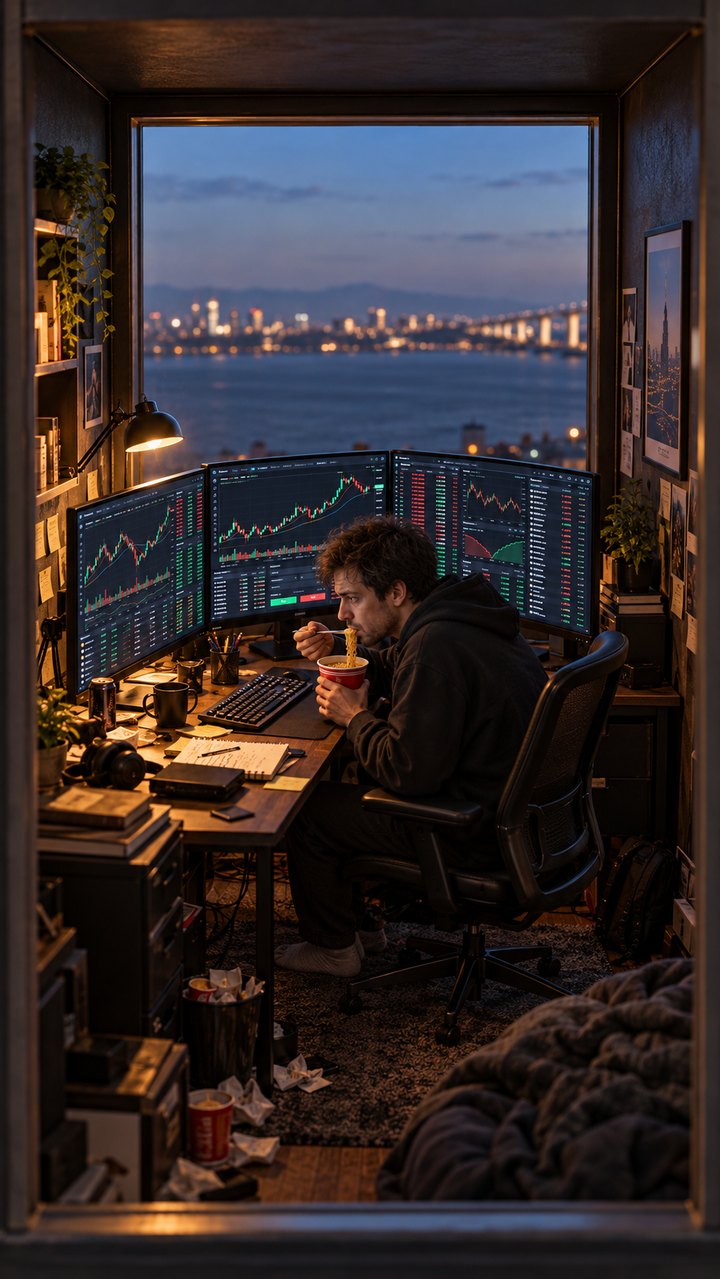
Una sala de trading desordenada por la noche con vistas a la ciudad y sin ningún gigante en la ventana.
Demasiado caótico, y el gigante no aparece.
La sala de yoga con el trader de la sala anterior aún visible a la izquierda.
El trader de la habitación antigua sigue en plano.
Un retrato de un hombre rubio con una forma de cabeza notablemente distinta a la de la referencia.
“Una persona totalmente distinta”.
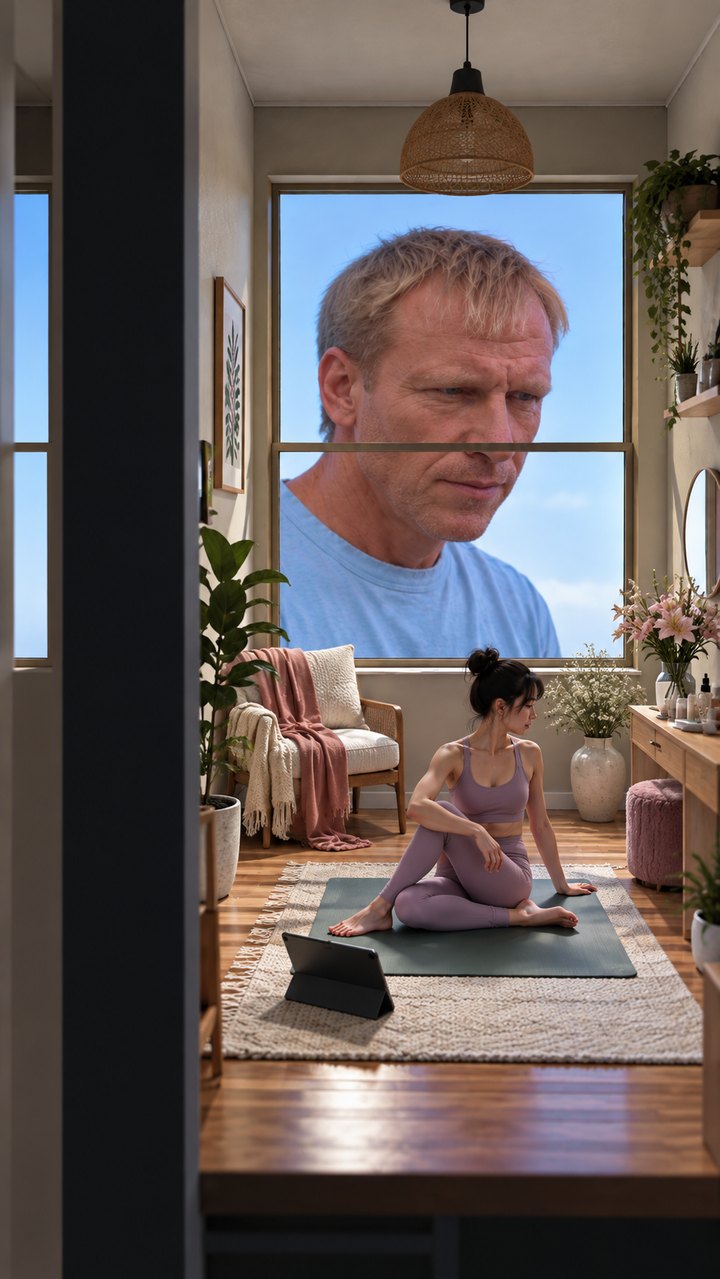
El rostro del gigante se divide entre dos ventanas como si fueran dos personas.
Yo, dividido en dos ventanas.
La sala de yoga con una ventana visiblemente más pequeña que la de referencia.
Ventana al 78% del tamaño solicitado.

Cerca del final, proporcioné la geometría exacta en píxeles para la ventana y ambas personas, y pedí al chat que midiera su propio resultado. Informó de una ventana de 485 × 644 px frente a los 621 × 811 px del prompt: 136 px demasiado estrecha y 167 px demasiado corta. Un modelo que redibuja una imagen a partir de palabras no puede alcanzar cifras de píxeles exactas, por muy precisas que sean las palabras.

Imágenes, ronda 2: 11 imágenes, la mayoría al primer intento

La segunda ronda comenzó a partir de la mejor imagen de la ronda 1 y se ejecutó en Codex conectada a la plataforma easyai.video, con nuestras habilidades de imagen instaladas. Ocho solicitudes produjeron once imágenes. Seis de las ocho solicitudes fueron cambios nuevos, cada uno aprobado a la primera; las otras dos fueron correcciones, para la posición de la pared y la altura del suelo.

La imagen de la habitación del trader de la ronda 1, con un techo brillante y una luz inexplicable en el póster del coche.
Inicio: la mejor imagen de la ronda 1.
La misma habitación con una nueva iluminación mediante la lámpara de techo, con un rostro más nítido junto a la ventana.
1 · una fuente de luz, rostro más nítido.
La misma sala con los ojos del gigante dirigidos hacia abajo, hacia el trader.
2 · la atención en el trader.
La misma habitación moviéndose justo detrás de un muro divisorio oscuro, con el gigante solo en el borde de la ventana.
3 · la pared entre las salas.
La sala de yoga con la misma geometría y el gigante en la ventana.
4 · la sala de yoga.

Nada mágico cambió entre las rondas. Lo que cambió fue la forma de preguntar:

  1. Edita, no regeneres. Cada petición partía de la última imagen aprobada y mantenía todo lo que ya estaba bien.
  2. Un cambio por solicitud. Luz, luego el rostro, luego la mirada, luego el diseño. Nunca cuatro correcciones en un solo mensaje.
  3. Un trabajo por imagen de entrada. “La imagen 1 es el objetivo de edición principal. La imagen 2 solo aporta la franja izquierda.”
  4. Mide y luego ancla. En lugar de “haz la habitación más estrecha”, el prompt indicaba dónde estaban las cosas en el origen y a dónde debían ir: traslada la habitación 275 px a la derecha con una escala de 100%, el travesaño de la ventana se mantiene en y = 626.
  5. Usa una habilidad, no improvises. Las habilidades de imagen nombraban el caso de uso (composición, preservación de identidad) y escribían el prompt con la misma estructura cada vez.

Puedes hacer lo mismo en tu propio entorno. Tanto Codex como Claude Code cargan habilidades: una carpeta con instrucciones y, opcionalmente, scripts que el agente lee antes de actuar. En GitHub y otros recursos públicos hay una amplia gama de habilidades de imagen y vídeo disponibles. Elige las habilidades que mejor se adapten a tu modelo y tarea de montaje, y utilízalas para mejorar tus prompts automáticamente. La plataforma easyai.video incluye estas habilidades, además de los formatos de prompt que espera cada modelo de vídeo.

Vídeo, toma 1: toda la escena en un único plano de 8 segundos

Con las tres imágenes aprobadas, las primeras tomas de vídeo pedían todo en una sola generación: comer, darse cuenta, gritar, lanzar, disculparse, deslizarse a la siguiente sala. Como experimento, empecé con Google Flow generaciones gratuitas. Google Flow utilizó las tres imágenes como referencia; la toma 2 usó un prompt reescrito que identificaba al interlocutor de cada frase y seguía el rastro de la taza hasta la ventana trasera. Seedance 2.5 utilizó las imágenes como fotograma inicial, referencia de imagen y fotograma final, en su modo de referencia omni.

Toma 1

Google Flow

Comienza en nuestro fotograma, luego el gigante dice ambas líneas, antes de que se lance nada. La taza vuela hacia la cámara, no hacia la ventana, y el trader conserva su propia taza. La sala de yoga entra en escena en lugar de deslizarse.

Toma 2

Google Flow

Nuestro primer fotograma es ignorado: un arco de puerta y una habitación más iluminada. Aparecen dos gigantes, luego entra un hombre de tamaño real y lanza la taza. Nadie dice “Lo siento”. Termina en una sala de yoga diferente.

Toma 3

Seedance 2.5 · borrador 480p

La más cercana de las tres: la taza sale volando hacia nosotros y se estrella contra el cristal trasero, mientras la cámara se desliza hacia la sala de yoga. Renderizada como un borrador barato en 480p.

Las imágenes no eran el problema. El plano pedía demasiadas cosas a la vez, y el modelo omitía algunas y reordenaba otras.

Vídeo, toma 2: dos planos cortos a través de un fotograma compartido

La solución fue dividir la escena donde se rompe de forma natural. El plano A transcurre desde el fotograma inicial hasta el fotograma central en 3 segundos: el trader come y el gigante se eleva hacia la ventana. El plano B transcurre desde ese mismo fotograma central hasta el fotograma final en 6 segundos: la línea, el lanzamiento, la disculpa y el movimiento hacia la sala de yoga. Los dos planos comparten un fotograma, lo que les da una composición común en el montaje. En esta versión, el trader lanza sus auriculares en lugar del vaso de fideos: los fideos salpicados por la ventana resultaban desagradables de ver, y Seedance los dibujaba demasiado grandes.

Ambos planos se realizaron con Wan 3.0 en Higgsfield, a una resolución nativa de 1080 × 1920 y 30 fps con sonido generado.

Plano A · 3 s

Wan 3.0

El comerciante sigue comiendo y nunca levanta la vista; el gigante entra deslizándose y se establece en el fotograma central.

Plano B · 6 s

Wan 3.0

“¡Déjame en paz!”, los auriculares golpean el cristal y caen, “Lo siento”, y luego el deslizamiento hacia la sala de yoga, aterrizando en el fotograma final. Añadió algunas notas musicales al final, algo que el prompt descartaba.

A + B · 9 s

Unidos en el fotograma compartido

El rostro tiene una textura de piel ligeramente diferente en la segunda parte, por lo que el montaje se nota. Un modelo que pueda realizar un plano continuo, como Seedance, es preferible para la continuidad.

El mismo plano en MiniMax H3: modelo completo vs turbo

Luego volvimos a renderizar el plano B en MiniMax H3, usando nuestra propia copia del modelo con la cuota diaria de GPU de Hugging Face, con los mismos dos fotogramas, la misma historia y la misma semilla (42). La plataforma easyai.video primero reescribe el prompt al formato que espera H3; el prompt de abajo es lo que se introdujo en el modelo tras esa reescritura.

Plano B · Wan 3.0

1080 × 1920 · 30 fps

La referencia: cada movimiento en orden, llegando al fotograma final.

Plano B · H3 completo

768 × 1344 · 24 fps · 28 pasos

Comparable con Wan 3.0 en este plano: la línea, el lanzamiento, la disculpa y el movimiento funcionan. Menor resolución; consume parte de la cuota diaria de GPU.

Plano B · H3 turbo

768 × 1344 · 24 fps · 6 pasos

Cumple con los puntos de la historia, pero el rostro grande, los auriculares y el movimiento entre habitaciones lo delatan.

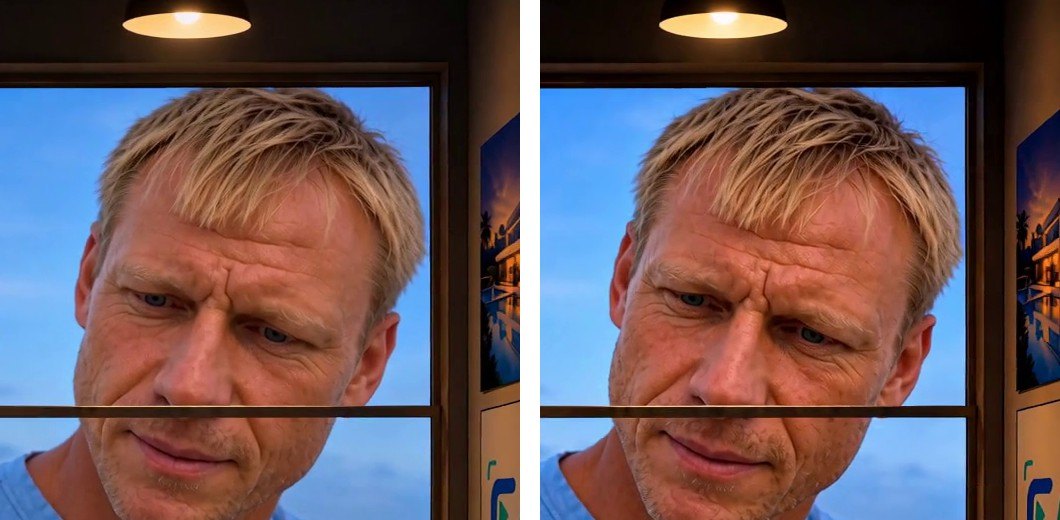
El rostro del gigante en el mismo momento: H3 completo a la izquierda y H3 turbo a la derecha; la versión turbo tiene manchas oscuras moteadas en la piel.
En el mismo instante, a los 1.6 s del plano B, a tamaño completo. Izquierda: H3 completo. Derecha: H3 turbo, con manchas oscuras moteadas por la piel.
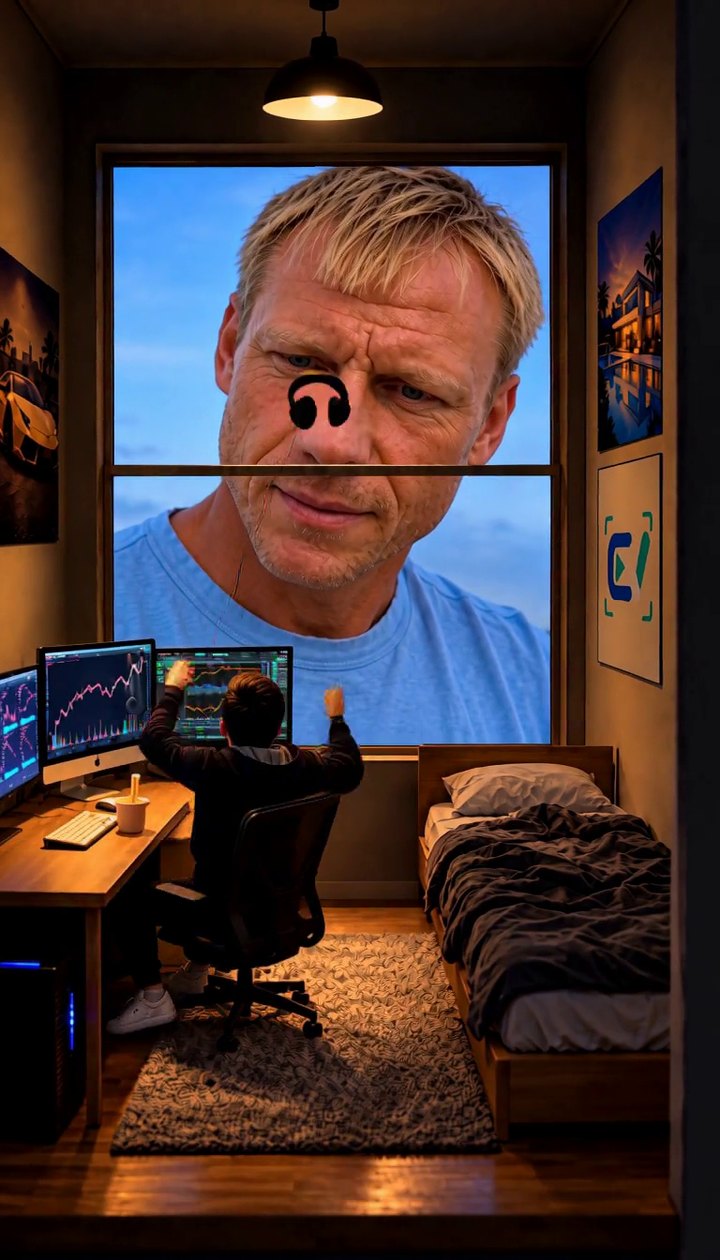
H3 fotograma turbo donde los auriculares lanzados aparecen como un icono negro plano en la nariz del gigante.
Turbo, 2.0 s: los auriculares parecen un icono plano pegado en la cara, no un objeto en movimiento.
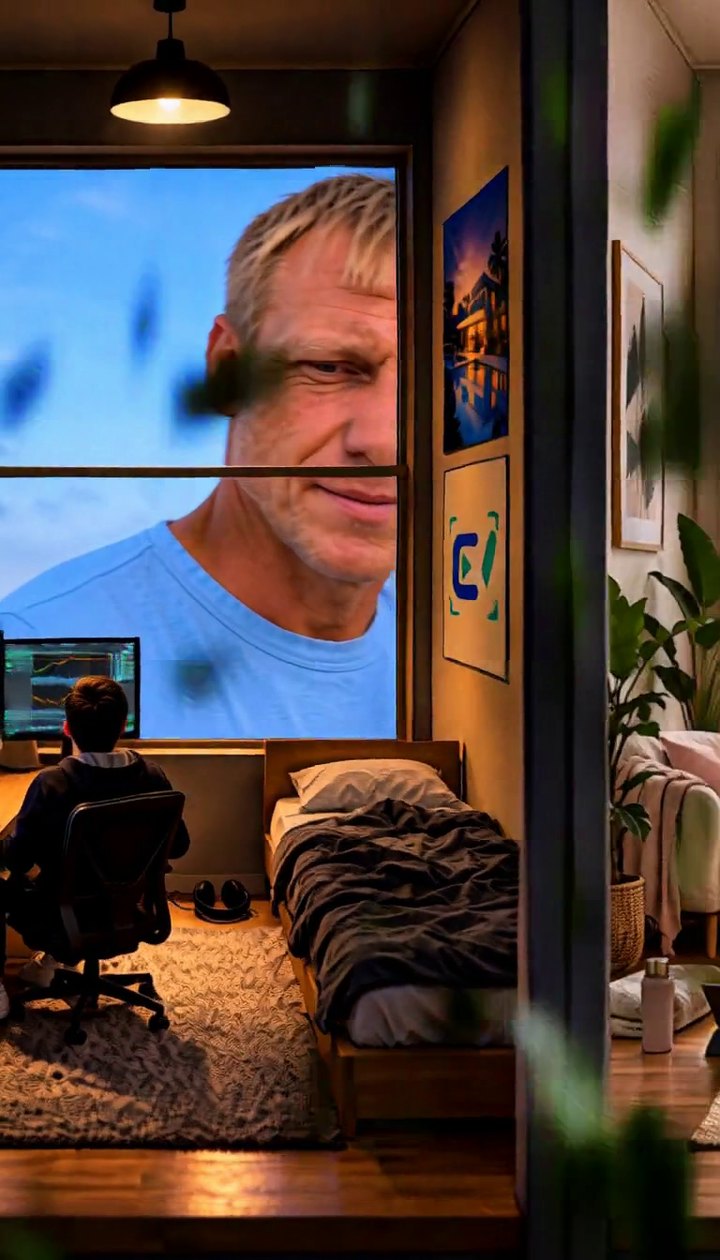
Fotograma H3 turbo durante el movimiento entre habitaciones, con hojas que nadie pidió cruzando el primer plano.
Turbo, 4.3 s: nadie pidió que las hojas se desplazaran por el primer plano durante el movimiento.

Turbo es para borradores. Es útil para planificar el movimiento de cámara o probar si los fotogramas funcionan. Cuando un rostro ocupa todo el plano, renderiza la toma con el modelo completo.

Resumen de costes por modelo

Las cruces rojas marcan tomas inaceptables. Los checks amarillos marcan tomas cercanas al objetivo con inconsistencias residuales; para Seedance, estas incluyen fideos demasiado grandes. Cada fila de la tabla cubre un modelo y una plataforma, con el coste total del metraje detallado.

Modelo · plataformaMetrajeResultadoBase de costesAprox. EUR
Google Flow2 × 8 s720 × 1280Créditos diarios gratuitos€0
Borrador de Seedance 2.5 · Higgsfield8 s480 × 85424 créditos€1.05
Wan 3.0 · Higgsfield3 s + 6 s1080 × 1920 · 30 fps31.5 créditos (3.5 por segundo)€1.38
MiniMax H3 completo · Hugging Face6.58 s768 × 1344 · 24 fps≈ 10.9 / 40 minutos de GPU diarios (27.3%)€0.073
MiniMax H3 turbo · Hugging Face6.58 s768 × 1344 · 24 fps≈ 4.2 / 40 minutos de GPU diarios (10.5%)€0.028

Las estimaciones de Higgsfield se basan en el plan registrado de $49 / 1,000 créditos, con todos los créditos utilizados. Las estimaciones de Hugging Face prorratean su suscripción mensual de $9 en 30 días, y luego multiplican esa parte diaria por el porcentaje de cuota en los registros de ejecución, incluyendo el condicionamiento. Estos son costes de suscripción asignados, no facturas por ejecución; la cuota no utilizada aumenta el coste efectivo.

Conversión: $1 ≈ €0.893, redondeado según el tipo de referencia del BCE. Los planes y las cuotas pueden cambiar; consulta los precios de Higgsfield y Hugging Face PRO para tu cuenta.

Conclusiones

  1. Diseña primero las imágenes clave y luego anima entre ellas. Los fotogramas compartidos ayudan a alinear una escena de varios planos, pero comprueba la textura de la piel y la iluminación en la unión.
  2. Edita la imagen aprobada en lugar de pedirla de nuevo. Un cambio por solicitud, un trabajo por imagen de entrada, posiciones reales en lugar de adjetivos.
  3. Los modelos Turbo son para borradores. Renderiza las tomas finales con el modelo completo cuando el rostro ocupe gran parte del plano.
  4. Un modelo de código abierto puede igualar a uno de pago en un plano determinado. H3 completo frente a Wan 3.0 aquí. Implementar un modelo OSS en una GPU puede ofrecer un resultado similar a un coste mucho menor que un modelo de pago mediante una API, dependiendo del uso del hardware y los costes de alojamiento.
  5. Usa habilidades para mejorar automáticamente los prompts de imagen y vídeo. Deja que instrucciones especializadas traduzcan una petición corta a la estructura y las restricciones que cada modelo necesita.

Ronda 1 · chat de ChatGPT

Uno de los prompts con geometría de píxeles exacta

Use gpt_mainref_shot1.png as the strict geometry and scale reference. Recreate the same dollhouse room proportions, camera position, perspective, window size, giant-person scale, and miniature-person scale. Change only the room content from the trader bedroom into a yoga/living room.
Final canvas: exactly 941 × 1672 px, vertical.
Do not change the camera position, focal length, room depth, wall proportions, floor perspective, or window proportions from gpt_mainref_shot1.png.
Main window geometry must match gpt_mainref_shot1.png exactly:
outer window frame: x=169 to 789, y=197 to 1007
outer window size: 621 × 811 px
visible glass area: x=193 to 767, y=230 to 988
glass size: 575 × 759 px
horizontal window divider: x=181 to 779, y=620 to 637
window center approximately x=479
the window must occupy about 66% of the entire image width
do not make the window smaller
do not move the bottom edge of the window upward
Behind the window is one giant adult man. Use the supplied male portrait reference for identity and pose. Preserve the same face proportions, head shape, nose, jaw, forehead, hairline, eye spacing, skin texture, light blond hair, stubble, light-blue T-shirt, and body proportions.
The giant man must have the same scale as the person in gpt_mainref_shot1.png:
head from top of hair to bottom of chin approximately x=292 to 710, y=228 to 824
head size approximately 419 × 597 px
visible shoulders and upper torso extend across almost the entire 575 px width of the window
the giant person must visually fill the window, not appear distant
his head and shoulders must remain much larger than the miniature person inside the room
Pose of giant man:
body turned approximately 25 to 30 degrees toward screen-right
shoulders turned by the same angle as the head
head slightly turned toward screen-right
eyes looking downward and inward into the room at the woman
expression curious and observant
do not make him look toward the camera
do not reduce his face size
do not shorten or round his head
do not create a second copy of him anywhere
Room geometry must preserve the same apparent size as gpt_mainref_shot1.png. The floor, ceiling, left wall, right wall, and back wall must occupy the same proportions. The camera remains outside the dollhouse, looking slightly downward into the room from the same elevated frontal angle.
On the extreme left, include a narrow slice of the previous room followed by a full-height dark dividing wall. The dividing wall must run continuously from the top edge to the bottom edge of the image and clearly separate the two rooms. The previous room must occupy only a very narrow strip and must not contain any visible person.
Replace the trader bedroom with a bright, realistic yoga/living room.
Inside the new room:
one young adult woman doing yoga on a mat
one tablet standing in front of her, showing a yoga instruction video
one comfortable chair
a soft dress and light fabric casually draped over the chair
one small dressing table on the right side with a few cosmetic bottles
a vase with flowers
minimal tasteful plants
no bed
no desk with computers
no paper
no garbage bin
no cluttered trash
The miniature woman must use approximately the same scale as the trader in gpt_mainref_shot1.png.
Target miniature-person scale:
overall body region approximately 265 × 438 px
top of head around y=925 to 950
lowest visible body point around y=1360
do not place her higher in the frame
do not enlarge her beyond the trader’s scale
she must remain clearly miniature compared with the giant man outside
Place the yoga woman lower in the composition, around the lower central area of the room. Her head should begin approximately where the trader’s head begins in the reference. The majority of her body must stay below the bottom edge of the window.
Yoga mat:
place it low in the frame
approximately x=185 to 710
approximately y=1180 to 1510
roughly 525 × 330 px
keep perspective aligned with the floor exactly like the rug area in gpt_mainref_shot1.png
The woman is seated in a clear seated spinal twist yoga pose. Her torso remains upright. One hand supports her on the mat. Her legs are folded. The tablet is positioned in front of the mat near the lower-left edge of the mat, angled toward her.
Lighting:
natural daylight only, entering through the giant window
neutral soft daylight
ceiling lamp present but switched off
no warm yellow glow
no wall lamps
no hidden artificial lighting
no cinematic orange lighting
room illumination must come primarily from the window
Keep the room realistic and naturally lived-in, but clean.
Critical constraints:
window size must remain exactly equivalent to gpt_mainref_shot1.png
giant man scale must remain exactly equivalent to gpt_mainref_shot1.png
miniature woman scale must remain equivalent to the trader scale in gpt_mainref_shot1.png
woman must be positioned low in the composition
camera must not zoom out
camera must not move backward
do not increase visible wall space around the window
do not shrink the window
do not shrink the giant face
do not create duplicated body parts or duplicated people
do not show any part of the giant man inside the narrow previous-room strip on the far left
preserve one continuous architectural dividing wall from ceiling to floor
photorealistic, realistic lens perspective, consistent scale, high detail, 9:16 composition.

Ronda 2 · Codex con habilidades de imagen

La corrección de geometría que funcionó

Use case: compositing. Generate one corrected photorealistic 9:16 dollhouse room-reveal keyframe, 941x1672 composition. Image 1 (mf1_sharp_reference_face) is the authoritative edit target for exact room geometry, object sizes, vertical positions, furnishings, person, face identity, textures and light. Image 2 (mf1_partition_reveal) supplies ONLY the left foreground strip and the giant man's partial-face placement. Image 3 (pasted plate) demonstrates the intended right-side cropping of the original room, keeping its proportions.

GEOMETRY IS THE PRIMARY EDIT. The left foreground strip in image 2 measures approximately 275 pixels of a 941-pixel width: neighboring-room glimpse at x=0..159, dark vertical dividing wall at x=160..274. Preserve this strip in the corrected frame. The remaining x=275..940 must show the LEFTMOST 666 pixels of image 1 at precisely its ORIGINAL SCALE and ORIGINAL HEIGHT. Translate image 1's room scene 275 pixels to the RIGHT and allow its rightmost 275 pixels to fall beyond the right border. This is a lateral camera reveal across a continuous dollhouse set. Keep the original room width and object proportions, expressed through partial offscreen framing. Use translation and clipping, with scale fixed at 100 percent. Maintain the source vertical coordinates throughout. Concrete anchors: original pendant center at x about 470 becomes x about 745, staying at y about 150; original window left glazing edge x about 193 becomes x about 468, with window top staying y about 230 and horizontal crossbar staying y about 626. The original window extends past the right frame border. Original bed left edge x about 593 becomes x about 868, so ONLY a narrow portion of the bed is visible at the extreme right. The original trader, chair and three monitors keep their exact source sizes and shift right by 275 pixels. The car poster remains its original size and shifts right identically. The original right wall artwork is beyond the frame edge. The rug and floor keep their original scale, pattern and vertical positions. The foreground strip aligns naturally with the room's open front.

FACE CHANGE: keep the same sharp blond man's identity, realistic skin, hair and original head scale from image 1, but move him laterally OUTSIDE the window to its left, as in image 2. Just a narrow sliver of blond hair, forehead, one eye, cheek and jaw peeks into the glazing along its LEFT edge, approximately x=468..525 in the final composition. The rest of the visible window is blue evening sky. Preserve the window frame and crossbar foreground occlusion. This partial visibility is achieved by the window edge clipping his head; preserve realistic head proportions.

World contract: same seated young man with glasses, black hoodie, dark trousers and white trainers at the same crypto workstation; same wood furniture and warm floor, dark rumpled bedding wherever visible, warm-white downward-facing pendant illumination with physically consistent falloff and shadows, softly dark ceiling, blue evening sky outdoors, crisp photorealistic facial detail. Preserve the source lighting and colors. Deliver exactly one corrected still with the room at full original scale and the right-side framing naturally clipped.

Google Flow · toma 1 · 8 s, tres imágenes de referencia

Prompt utilizado para la toma 1

Create an 8-second photorealistic cinematic video with synchronized English dialogue, in vertical 9:16.

REFERENCE ROLES
Opening: @generated/images/mf1_partition_reveal_corrected.png. Begin on this exact trader-room composition, including the foreground partition, neighboring-room sliver, original room proportions, floor height, tall window, pendant, workstation and cropped bed.
Intermediate appearance reference, around 2 seconds: @generated/images/mf1_looking_at_guy.png. Match the giant observer’s recognizable face, blond hair, blue eyes, realistic skin texture, light-blue T-shirt, head scale and downward gaze toward the seated trader. This guides his appearance during the encounter; camera movement determines the framing.
Ending: @generated/images/lf1_partition_reveal_corrected.png. Land on this exact yoga-room composition and final observer pose.

CAMERA AND GEOGRAPHY
One continuous lateral dolly to camera-right along the open front of a physical dollhouse. The trader room is left of the yoga room. As the camera travels right, the fixed rooms slide left across the image and their dividing wall passes through the foreground. Keep camera height, viewing direction and focal length constant. Preserve the original width and height of each room: furniture and architecture retain their dimensions and leave the image through natural cropping. Maintain a common floor level and consistent miniature scale. The observer remains a single giant man outside the windows throughout.

0.0-2.2 SECONDS
The miniature trader, wearing glasses, a black hoodie, dark trousers and white trainers, eats instant noodles from a cup with a fork while watching his three monitors. The camera glides slowly right from the opening reveal toward a clearer view of the workstation. Outside, the giant blond man leans into the window from its left edge until his face is clearly visible. He tilts his head and looks directly down at the trader, matching the intermediate appearance reference. His expression is curious and mildly intrusive.

2.2-3.4 SECONDS
The trader notices him, pauses with the fork raised, turns his head and upper body toward the window and snaps angrily in English: “Leave me alone!” His mouth movement matches the words. The observer listens.

3.4-4.2 SECONDS
Immediately after finishing the line, the trader throws the noodle cup from his hand toward the observer’s face. The cup travels away from the trader and strikes the INSIDE surface of the window glass. Broth and noodles splatter on the interior glass directly in front of the giant’s face. The glass stays intact and separates the observer from the cup and splatter.

4.2-4.8 SECONDS
The observer flinches, blinks and replies apologetically in English: “Sorry!” His mouth movement matches the word. He then withdraws from the trader’s window and moves physically right outside the building toward the neighboring yoga-room window.

4.8-7.6 SECONDS
The camera continues its rightward dolly, smoothly traversing the foreground dividing wall and revealing the brighter yoga room. The trader room and its splattered window slide out to the left. The woman wears a mauve sports bra and leggings, with dark hair in a bun. She remains seated low on her mat in the reference pose, calmly following the tablet on the floor. Her gaze stays on the tablet. Preserve the cream chair, pink throw, plants, bottle, rug and visible furniture from the ending reference. The house poster and EasyAI artwork remain in the narrow neighboring-room strip left of the partition.

7.6-8.0 SECONDS
The camera gently settles into the ending reference. Match its floor height, window dimensions and placement, woman’s position and pose, furniture scale, partition thickness and framing. The giant has reached the exact final head position, orientation and window-relative scale shown there, wearing the same light-blue T-shirt. He holds that pose while the woman continues focusing on her tablet.

LOOK AND SOUND
Keep the trader room’s warm pendant lighting and the yoga room’s soft natural daylight, with stable exposure and reference-matched colors. Natural facial animation, grounded body motion and believable miniature materials. Maintain continuous spatial movement throughout, with transitions produced by the camera passing the physical wall. Sound consists of quiet computer hum, fork and noodle sounds, the trader’s shout, a cup impact and wet glass splatter, the observer’s brief apology, then calm yoga-room ambience. Only the two specified spoken lines. Ambience and effects form the soundtrack; the image remains free of captions and graphic overlays.

Google Flow · toma 2 · 8 s, tres imágenes de referencia

Prompt utilizado para la toma 2

Create an 8-second photorealistic vertical 9:16 video with synchronized English dialogue.

REFERENCES
First frame: @generated/images/mf1_partition_reveal_corrected.png - opening trader-room composition.
Intermediate appearance reference: @generated/images/mf1_looking_at_guy.png - giant observer’s identity, scale and downward gaze toward the trader.
Last frame: @generated/images/lf1_partition_reveal_corrected.png - final yoga-room composition and observer pose.

CHARACTER AND SPEAKER ASSIGNMENTS
TRADER: the miniature young man INSIDE the bedroom, wearing glasses, a black hoodie, dark trousers and white trainers. He alone says: “Leave me alone!” He throws the noodle cup.
OBSERVER: the giant blond man OUTSIDE the rear window, wearing a light-blue T-shirt. He quietly watches the trader and trading monitors. His sole spoken line is: “Sorry!”

GEOGRAPHY
The camera views the miniature room through its open front. The trader is inside, between the camera and the rear window. The giant stands outside, behind that window. The window glass physically separates them. The cup travels from the trader toward the BACK of the room, away from the camera, and strikes the interior surface of the rear window directly in front of the giant’s face.

0.0-2.5 SECONDS - SILENT OBSERVATION
Begin on the first reference. The trader eats noodles while watching his three monitors. The giant gradually leans into view from the window’s left edge, matching the intermediate reference. His eyes move naturally between the trader and the screens below. His lips remain together, his expression quietly curious, his hands below the window sill.

2.5-3.3 SECONDS - THE TRADER SPEAKS
The trader notices the giant, puts his fork on the desk, and turns his head and shoulders toward the rear window. His mouth is visibly readable in profile as he angrily shouts in English: “Leave me alone!” Use a young male voice originating inside the room. During this entire line, the giant keeps his lips together and listens with a surprised expression.

3.3-4.1 SECONDS - THE TRADER THROWS
The trader transfers the SAME cup he was eating from into his right hand, draws that arm back, then swings toward the rear window and releases it. Show the release and continuous flight clearly. His throwing hand is visibly empty afterward. The separate cup already resting on the desk stays there.

The thrown cup remains miniature, matching the trader’s hand. It recedes through the room toward the rear glass, becoming slightly smaller with distance. It strikes the pane in front of the observer’s face. Broth and noodles splash onto that rear pane and cling to it; the cup falls inside beneath the window. The glass remains intact. The foreground viewing opening and camera view remain clean. The giant stays outside throughout.

4.1-4.6 SECONDS - THE OBSERVER REPLIES
After the impact, the giant gives one startled blink. Only now his lips move as he softly says in English: “Sorry!” Use a distinct mature male voice originating outside the window. The trader’s mouth stays closed during this reply.

4.6-8.0 SECONDS - NEXT ROOM
The giant withdraws and moves right outside the building. The camera continues its smooth lateral dolly right along the dollhouse front. The fixed trader room slides left; the physical dividing wall passes through the foreground, revealing the yoga room. Maintain camera height, focal length, room dimensions, window geometry, shared floor level and furniture scale.

Gently settle into the last reference by 7.6 seconds and preserve that composition through 8.0 seconds. The woman in mauve yoga clothes remains focused on her tablet in the reference pose. The giant reaches the reference’s exact window-relative position and head orientation.

STYLE AND AUDIO
One continuous shot. Preserve each reference room’s lighting, materials and architectural proportions. Natural restrained acting. Sound: computer hum, eating sounds, the trader’s “Leave me alone!”, cup release, rear-window impact, wet splatter, the observer’s “Sorry!”, then quiet yoga-room ambience. The two lines occur separately, with the visible speaker’s lips synchronized to each line. Ambience and effects provide the soundtrack.

Seedance 2.5 · borrador 480p · omni-referencia, fotograma inicial + imagen de referencia + fotograma final

Prompt utilizado para este borrador

8-second contemporary digital comedy scene inside a physical miniature dollhouse. One continuous take: a giant’s quiet curiosity provokes a miniature trader, then the camera reveals the calm neighboring yoga room.

MODEL: Seedance 2.5, omni-reference.
FORMAT: 9:16, 8.0 seconds, photoreal digital cinema.

REFERENCES
@Image1 - generated/images/mf1_partition_reveal_corrected.png, supplied as START FRAME. Preserve its opening composition, architectural proportions, floor height, window geometry, furniture and lighting. Use it for the opening only; the camera subsequently travels right.
@Image2 - generated/images/mf1_looking_at_guy.png, supplied as IMAGE REFERENCE. Take the giant observer’s exact identity, blond hair, blue eyes, light-blue T-shirt, face scale and downward gaze. Use this appearance during the trader encounter; do not insert this still as a separate shot.
@Image3 - generated/images/lf1_partition_reveal_corrected.png, supplied as END FRAME. Match its final composition, yoga-room geometry, woman’s pose, furniture and observer orientation. Its interior belongs only to the neighboring yoga room.

SUBJECTS AND SPEAKERS
TRADER: miniature young man inside the room, glasses, black hoodie, dark trousers, white trainers. He alone says “Leave me alone!” and throws the noodle cup he is holding.
OBSERVER: giant blond man outside the rear window, matching @Image2, wearing a light-blue T-shirt. His only line is “Sorry!”
WOMAN: miniature woman in the yoga room, dark hair in a bun, mauve sports bra and leggings. She remains silent and focused on her tablet.

STYLE: reference-matched lens perspective, deep enough focus to read the trader and observer together, restrained facial acting, natural skin texture and cloth movement. Must feel like a photographed miniature set with a real person outside, not generated footage.
COLOR: warm brown and charcoal in the trader room; cream, muted mauve and oak in the yoga room; blue daylight outside. Stable reference-matched exposure.
ENVIRONMENT: trader room left, yoga room right, connected by a common floor level and separated by a thick structural wall. Warm overhead pendant illuminates the trader; daylight enters through the rear windows. Architecture and furniture remain fixed.

CAMERA: physical lateral dolly to camera-right along the open dollhouse front. Constant height, viewing direction and focal length. Rooms move left across the image through parallax and natural cropping. Motion preset: none. The following numbered beats are phases within the same shot, not cuts.

Shot 1 [0.0s-2.2s] - wide room view from the opening reference: the trader continues eating and watching his three monitors. The observer leans into view until his appearance matches @Image2, quietly looking between the trader and monitors. His lips stay closed and his hands remain below the sill.
Camera: slow rightward dolly.
SFX: faint computer hum and fork contact.

Shot 2 [2.2s-3.3s] - same wide view and angle: the trader puts down his fork and turns toward the rear window while retaining his cup. The miniature trader angrily says, “Leave me alone!” His lips alone articulate these words; the observer listens with his lips closed.
Camera: continue the slow rightward dolly, keeping both faces visible.
SFX: the trader’s young male voice originates inside the room. Realistic lip articulation, no exaggerated mouth opening, no head turns while speaking.

Shot 3 [3.3s-4.1s] - same room view: the trader draws back his cup-holding arm, swings toward the rear window and releases that same miniature cup. Show hand, release and flight as one connected action. His hand is empty afterward. The cup travels away from the camera into the back of the room, becoming smaller with distance, and strikes the interior glass directly in front of the observer’s face. Broth and noodles stick to the rear pane; the cup drops inside below it. The separate cup on the desk stays in place. Glass remains intact; the observer stays outside behind it.
Camera: continue rightward, retaining the throwing hand and rear pane in view.
SFX: cup impact and wet splatter.

Shot 4 [4.1s-4.6s] - same room view: the observer blinks at the impact, then softly says, “Sorry!” Only the giant observer’s lips articulate this word. The trader’s mouth stays closed.
Camera: continue the rightward dolly.
SFX: distinct mature male voice from outside, brief apologetic delivery with realistic lip articulation.

Shot 5 [4.6s-7.5s] - wide view along the same dollhouse front: the observer withdraws from the trader window and moves right outside the building. The camera passes the physical dividing wall, revealing the yoga room. The woman stays seated in her reference pose, eyes on the tablet. The observer arrives at the yoga window and settles into @Image3’s exact head position and orientation.
Camera: continuous rightward translation, gently decelerating into the end-frame composition.
SFX: computer hum fades with distance into quiet room ambience.

Shot 6 [7.5s-8.0s] - held wide composition matching @Image3: preserve floor height, window size and placement, partition thickness, woman’s position, furniture and observer scale. Everyone holds the established ending.
Camera: settled and locked.
SFX: silence holds the final 0.5 seconds.

AUDIO: the two assigned English lines are clear and prominent; synchronized effects are secondary, room ambience subtle.
- No music, no library audio, no voiceover narration, no on-screen text, no subtitles, no added logo.

CONSTRAINTS: one unbroken continuous take. No cuts, dissolves or black frames. No zoom or focal-length change. The trader alone delivers the angry line and throws his own cup. The observer watches silently until his apologetic reply. Preserve each person’s identity and wardrobe. Preserve miniature-to-giant scale, room dimensions and window geometry. The woman’s attention remains on the tablet. Existing wall artwork stays part of the set.
Stable face throughout. No morphing. No deformation. Photoreal cinematic finish.

Wan 3.0 · plano A · desde el fotograma inicial hasta el fotograma medio, 3 s

Prompt utilizado para el plano A

3-second contemporary digital comedy shot inside a physical miniature dollhouse. One continuous take: a miniature trader eats noodles at his desk while a giant, unnoticed, slowly rises into view behind his rear window.

FORMAT: 9:16, 3.0 seconds, photoreal digital cinema with native sound.

START AND END: open exactly on the supplied start frame (trader room; trader holding his noodle cup near his mouth; only a sliver of the giant observer's face visible at the far left edge of the rear window) and end exactly on the supplied end frame (same room; the observer's whole face filling the rear window, looking down at the trader). Keep both frames' composition, proportions, floor height, window geometry, furniture, desk items and lighting.

TRADER: miniature young man at the desk, glasses, black hoodie, dark trousers, white trainers. He eats continuously for the whole shot: cup held near his mouth in one hand, lifting forkfuls of noodles, chewing, eyes on his three monitors. He never notices the observer, never turns, never speaks. Black over-ear headphones lie untouched on the desk beside the keyboard.
OBSERVER: giant blond man, blue eyes, light-blue T-shirt, outside the rear window; exactly the man in the end frame. He moves from almost out of view at the left edge across and into the window, curious, settling into the end frame's head position, angle and downward gaze. Lips closed, silent, hands below the sill.

STYLE: frame-matched lens perspective, deep focus holding trader and observer together, restrained acting, natural skin and cloth. A photographed miniature set with a real person outside, not generated footage.
COLOR: warm brown and charcoal room under a warm pendant; blue daylight outside the window.
ENVIRONMENT: the trader room only: desk with three monitors, keyboard, headphones, bed, rug, wall artwork. Architecture and furniture stay fixed.

CAMERA: very slight physical dolly to camera-right along the open dollhouse front, matching the small shift between the start and end frames; constant height, direction and focal length. No zoom.

[0.0s-2.5s] The trader keeps eating - forkfuls lifted and chewed, eyes on the monitors. The observer glides in from the left edge of the rear window, his face rising and sliding across until it fills the window, quietly watching the trader eat. SFX: faint computer hum, fork against the cup, soft slurping, chewing.

[2.5s-3.0s] Held composition matching the end frame: the observer's face filling the rear window, eyes on the trader; the trader still eating, unaware. Camera settled.

AUDIO: eating sounds and computer hum only; subtle room ambience. No dialogue, no music, no narration, no on-screen text, no subtitles, no logo.

CONSTRAINTS: one unbroken take; no cuts, dissolves, black frames or zoom. Nobody speaks. The trader keeps eating and never looks at the window. The headphones stay on the desk. Preserve identities, wardrobe, miniature-to-giant scale, room dimensions, window geometry and desk items. Stable faces throughout, no morphing, no deformation, photoreal cinematic finish.

Wan 3.0 · plano B · del fotograma medio al fotograma final, 6 s

Prompt utilizado para el plano B

contemporary digital comedy shot inside a physical miniature dollhouse. One continuous take: a miniature trader, interrupted while eating, snaps at the giant watching him through his window and throws his headphones at him; the giant apologizes and moves on, and the camera reveals the calm neighboring yoga room.
FORMAT: photoreal digital cinema with native sound.
START AND END: open exactly on the supplied start frame @[Image 1](image_1) (trader room; trader eating; the giant observer's whole face filling the rear window, looking down at him) and end exactly on the supplied end frame @[Image 2](image_2) (yoga room; observer full-face at its window). Keep both frames' composition, proportions, floor height, window geometry, furniture and lighting.
TRADER: miniature young man at the desk, glasses, black hoodie, dark trousers, white trainers, noodle cup in hand. Black over-ear headphones lie on the desk beside the keyboard, at his left. He alone says "Leave me alone!" and throws those headphones.
OBSERVER: giant blond man, blue eyes, light-blue T-shirt, outside the rear windows; exactly the man in both frames. His only line is "Sorry!"
WOMAN: miniature woman in the yoga room, dark hair in a bun, mauve sports bra and leggings; silent, focused on her tablet.
STYLE: frame-matched lens perspective, deep focus holding trader and observer together, restrained acting, natural skin and cloth. A photographed miniature set with a real person outside, not generated footage.
COLOR: warm brown and charcoal trader room; cream, muted mauve and oak yoga room; blue daylight outside.
ENVIRONMENT: trader room left, yoga room right, one floor level, a thick structural wall between them. Warm pendant over the trader; daylight through the rear windows. Architecture and furniture stay fixed.
CAMERA: physical lateral dolly to camera-right along the open dollhouse front; constant height, direction and focal length; rooms slide left through parallax. The beats below are phases of one shot, not cuts.
[0.0s-1.4s] The trader stops eating, sets the cup down on the desk, turns to the rear window and angrily says "Leave me alone!" Only his lips move; the observer listens, lips closed. Slow rightward dolly, both faces visible. Young male voice from inside the room, realistic lip sync.
[1.4s-2.3s] The trader snatches the black headphones from beside the keyboard and throws them hard at the rear window, straight at the observer's face - grab, swing, release and flight as one connected action; his hand is empty afterward. The headphones fly away from camera, shrinking with distance, hit the inside of the glass in front of the observer's face and drop to the floor below the window. The cup stays on the desk; the glass stays intact; the observer stays outside. SFX: hard plastic thud on glass, headphones clattering on the floor.
[2.3s-2.9s] The observer blinks at the impact and softly says "Sorry!" Only his lips move; the trader's mouth stays closed. Mature male voice from outside, realistic lip sync.
[2.9s-5.5s] The observer withdraws and moves right outside the building. The camera passes the dividing wall, revealing the yoga room; the woman stays seated, eyes on the tablet. The observer arrives at the yoga window and settles into the end frame's exact head position. Continuous rightward translation, decelerating into the end-frame composition. SFX: computer hum fades into quiet room ambience.
[5.5s-6.0s] Held composition matching the end frame - floor height, window placement, wall thickness, the woman's position, observer scale. Camera settled. Silence holds the final 0.5 seconds.
AUDIO: the two English lines clear and prominent; effects secondary; subtle ambience. No music, no narration, no on-screen text, no subtitles, no logo.
CONSTRAINTS: one unbroken take; no cuts, dissolves, black frames or zoom. The trader alone speaks the angry line and throws the headphones; the noodle cup is never thrown. The observer is silent until "Sorry!". Preserve identities, wardrobe, miniature-to-giant scale, room dimensions and window geometry. Existing wall artwork stays. Stable faces throughout, no morphing, no deformation, photoreal cinematic finish.

MiniMax H3 · plano B · mismos fotogramas, semilla 42

Prompt enviado a ambas ejecuciones de H3

How the reference pictures align with the target video - Picture 1 (from Shot 1) aligns with the 0.00-second mark of the target video; Picture 2 (from Shot 1) aligns with the 6.58-second mark of the target video.

integrated_multimodal_description: [Shot 1] Photoreal digital cinema, cinematic, a single continuous lateral dolly shot from left to right along the front of a miniature dollhouse, maintaining constant height, direction, and focal length. The scene opens exactly on <Picture 1>: a miniature trader in a warm brown and charcoal room, seated at a desk with three monitors displaying financial charts, a noodle cup in hand, black over-ear headphones resting on the desk to his left. He wears glasses, a black hoodie, dark trousers, and white trainers. Outside the rear window, a giant blond man in a light-blue T-shirt fills the frame, his face visible from forehead to chin, looking down at the trader. The room is lit by a warm pendant light above the desk; daylight streams through the rear windows. The camera begins a slow rightward dolly. At 00:01.400, the trader stops eating, sets the cup down, turns toward the rear window, and with a tight expression, says: <d>[English] Leave me alone!</d> His lips move in realistic sync; the observer’s lips remain closed. From 00:01.400 to 00:02.300, the trader snatches the headphones from the desk, swings his arm forward, and throws them hard at the rear window - a single connected motion. The headphones fly away from the camera, shrinking with distance, strike the inside of the glass directly in front of the observer’s face, and clatter to the floor below the window. The cup remains on the desk; the glass remains intact; the observer remains outside. SFX: hard plastic thud on glass, headphones clattering on floor. From 00:02.300 to 00:02.900, the observer blinks at the impact and softly says: <d>[English] Sorry!</d> His lips move in realistic sync; the trader’s mouth remains closed. From 00:02.900 to 00:05.500, the observer withdraws and moves right outside the building, the camera continuing its rightward dolly, passing the thick structural wall between rooms. The yoga room is revealed: cream walls, muted mauve accents, oak flooring, a woman in a mauve sports bra and leggings seated on a mat, focused on a tablet. The observer arrives at the yoga window and settles into the exact head position shown in <Picture 2>. The camera decelerates into the end-frame composition. From 00:05.500 to 00:06.000, the composition holds exactly as in <Picture 2>: floor height, window placement, wall thickness, the woman’s position, observer scale. The camera is settled. The final 0.5 seconds are silent.

overall_soundscape: The trader’s noodle cup clinks softly as he sets it down. A hard plastic thud and clatter as headphones strike the window and fall. The observer’s voice is clear and soft. Computer hum fades into quiet room ambience as the camera moves into the yoga room. The woman’s breath is shallow and steady; no other sounds.

non_diegetic_music: N/A

Crea un plano como este tú mismo

AI Video Starter es un taller intensivo de tres horas: idea, plan de rodaje, imágenes de referencia, generación, corrección de tomas fallidas y montaje, aplicado a tu propio vídeo corto.

Ver los talleres ↗